diff --git a/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_01.wav b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_01.wav
new file mode 100644
index 0000000..ec68606
Binary files /dev/null and b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_01.wav differ
diff --git a/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_02.wav b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_02.wav
new file mode 100644
index 0000000..7ca56c6
Binary files /dev/null and b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_02.wav differ
diff --git a/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_03.wav b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_03.wav
new file mode 100644
index 0000000..f16c56e
Binary files /dev/null and b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_03.wav differ
diff --git a/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_04.wav b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_04.wav
new file mode 100644
index 0000000..8d79867
Binary files /dev/null and b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_04.wav differ
diff --git a/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_06.wav b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_06.wav
new file mode 100644
index 0000000..3babc51
Binary files /dev/null and b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_06.wav differ
diff --git a/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_07.wav b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_07.wav
new file mode 100644
index 0000000..58d0df7
Binary files /dev/null and b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_07.wav differ
diff --git a/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_08.wav b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_08.wav
new file mode 100644
index 0000000..45b3daf
Binary files /dev/null and b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_08.wav differ
diff --git a/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_09.wav b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_09.wav
new file mode 100644
index 0000000..b06796e
Binary files /dev/null and b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_09.wav differ
diff --git a/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_10.wav b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_10.wav
new file mode 100644
index 0000000..8e569e8
Binary files /dev/null and b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_10.wav differ
diff --git a/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/guide_collect.wav b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/guide_collect.wav
new file mode 100644
index 0000000..29cbef8
Binary files /dev/null and b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/guide_collect.wav differ
diff --git a/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/guide_count.wav b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/guide_count.wav
new file mode 100644
index 0000000..19e029b
Binary files /dev/null and b/Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/guide_count.wav differ
diff --git a/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_01.wav b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_01.wav
new file mode 100644
index 0000000..ec68606
Binary files /dev/null and b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_01.wav differ
diff --git a/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_02.wav b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_02.wav
new file mode 100644
index 0000000..7ca56c6
Binary files /dev/null and b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_02.wav differ
diff --git a/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_03.wav b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_03.wav
new file mode 100644
index 0000000..f16c56e
Binary files /dev/null and b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_03.wav differ
diff --git a/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_04.wav b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_04.wav
new file mode 100644
index 0000000..8d79867
Binary files /dev/null and b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_04.wav differ
diff --git a/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_05.wav b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_05.wav
new file mode 100644
index 0000000..5cbbea0
Binary files /dev/null and b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_05.wav differ
diff --git a/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_06.wav b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_06.wav
new file mode 100644
index 0000000..3babc51
Binary files /dev/null and b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_06.wav differ
diff --git a/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_07.wav b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_07.wav
new file mode 100644
index 0000000..58d0df7
Binary files /dev/null and b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_07.wav differ
diff --git a/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_08.wav b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_08.wav
new file mode 100644
index 0000000..45b3daf
Binary files /dev/null and b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_08.wav differ
diff --git a/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_09.wav b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_09.wav
new file mode 100644
index 0000000..b06796e
Binary files /dev/null and b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_09.wav differ
diff --git a/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_10.wav b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_10.wav
new file mode 100644
index 0000000..8e569e8
Binary files /dev/null and b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/count_10.wav differ
diff --git a/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/guide_collect.wav b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/guide_collect.wav
new file mode 100644
index 0000000..29cbef8
Binary files /dev/null and b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/guide_collect.wav differ
diff --git a/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/guide_count.wav b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/guide_count.wav
new file mode 100644
index 0000000..19e029b
Binary files /dev/null and b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/guide_count.wav differ
diff --git a/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/selection.json b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/selection.json
new file mode 100644
index 0000000..b471e38
--- /dev/null
+++ b/SourceAssets/Audio/Voice/edited/20261004T161231511126Z_aa20f404/selection.json
@@ -0,0 +1,239 @@
+{
+ "schemaVersion": 1,
+ "runId": "20261004T161231511126Z_aa20f404",
+ "profileHash": "a5740d9db8a4aaebf08d0ac3b8f3225693f878aa2868143f01191a059e2680e8",
+ "catalogHash": "491c9cd0bb7068a47b33bdd0b19ece1ba634217ec0ed9cc3e2c5aa7bd3802755",
+ "selections": [
+ {
+ "id": "count_01",
+ "sourceRunId": "20261004T161148012934Z_47f3a009",
+ "sourceFile": "generated/20261004T161148012934Z_47f3a009/count_01.wav",
+ "sourceSha256": "cb7f5e25d8ba3e726b9557597002aef72c35e51edd6012defcb327728c10021f",
+ "editedFile": "edited/20261004T161231511126Z_aa20f404/count_01.wav",
+ "runtimeFile": "Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_01.wav",
+ "editedMetadata": {
+ "sha256": "13a882ce1620140d447635e14f2d4758045d5e348960c17386df1c720050c100",
+ "sampleRate": 44100,
+ "channels": 1,
+ "frames": 24696,
+ "duration": 0.56,
+ "peak": 0.344573974609375,
+ "rms": 0.07999517023563385,
+ "qualityWarnings": []
+ },
+ "review": "not_listened",
+ "status": "draft",
+ "processing": "polyphase resample to mono PCM16 44100 Hz; no speech trimming"
+ },
+ {
+ "id": "count_02",
+ "sourceRunId": "20261004T161231511126Z_aa20f404",
+ "sourceFile": "generated/20261004T161231511126Z_aa20f404/count_02.wav",
+ "sourceSha256": "ee8b600198b802248715beafe51848066ce4955c20ac600d5b577590372830cf",
+ "editedFile": "edited/20261004T161231511126Z_aa20f404/count_02.wav",
+ "runtimeFile": "Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_02.wav",
+ "editedMetadata": {
+ "sha256": "278dd0b6e96f2abca2237ff98eda453a011fa0b2e78d5575b7ddc9c9b3028b32",
+ "sampleRate": 44100,
+ "channels": 1,
+ "frames": 45864,
+ "duration": 1.04,
+ "peak": 0.47894287109375,
+ "rms": 0.09964785724878311,
+ "qualityWarnings": []
+ },
+ "review": "not_listened",
+ "status": "draft",
+ "processing": "polyphase resample to mono PCM16 44100 Hz; no speech trimming"
+ },
+ {
+ "id": "count_03",
+ "sourceRunId": "20261004T161231511126Z_aa20f404",
+ "sourceFile": "generated/20261004T161231511126Z_aa20f404/count_03.wav",
+ "sourceSha256": "572416e0d66821e1b939833cab328c23b5c97aef2233619428cd54c0603b6b12",
+ "editedFile": "edited/20261004T161231511126Z_aa20f404/count_03.wav",
+ "runtimeFile": "Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_03.wav",
+ "editedMetadata": {
+ "sha256": "4133b0150aa08e26f1b93b11d29ecab1282bbff236b3c92f8416e781109188c1",
+ "sampleRate": 44100,
+ "channels": 1,
+ "frames": 21168,
+ "duration": 0.48,
+ "peak": 0.8720703125,
+ "rms": 0.1623106449842453,
+ "qualityWarnings": []
+ },
+ "review": "not_listened",
+ "status": "draft",
+ "processing": "polyphase resample to mono PCM16 44100 Hz; no speech trimming"
+ },
+ {
+ "id": "count_04",
+ "sourceRunId": "20261004T161148012934Z_47f3a009",
+ "sourceFile": "generated/20261004T161148012934Z_47f3a009/count_04.wav",
+ "sourceSha256": "c37c335baa80dbdade6e8c6163eb2339cda307d187258306e881b55ab7149f79",
+ "editedFile": "edited/20261004T161231511126Z_aa20f404/count_04.wav",
+ "runtimeFile": "Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_04.wav",
+ "editedMetadata": {
+ "sha256": "c5c8c78ccd89011050d7317960a854130e3e445c8b92d23e9520eeb7490aa300",
+ "sampleRate": 44100,
+ "channels": 1,
+ "frames": 21168,
+ "duration": 0.48,
+ "peak": 0.396087646484375,
+ "rms": 0.07825528085231781,
+ "qualityWarnings": []
+ },
+ "review": "not_listened",
+ "status": "draft",
+ "processing": "polyphase resample to mono PCM16 44100 Hz; no speech trimming"
+ },
+ {
+ "id": "count_06",
+ "sourceRunId": "20261004T161231511126Z_aa20f404",
+ "sourceFile": "generated/20261004T161231511126Z_aa20f404/count_06.wav",
+ "sourceSha256": "235c4b6a73be845080af4a10508c433e3d6bf05cb4e0445cba18e23e367d51f7",
+ "editedFile": "edited/20261004T161231511126Z_aa20f404/count_06.wav",
+ "runtimeFile": "Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_06.wav",
+ "editedMetadata": {
+ "sha256": "d4800a23a73d1315987d9129d260baa0680621d6502351137845a6ee351c6274",
+ "sampleRate": 44100,
+ "channels": 1,
+ "frames": 45864,
+ "duration": 1.04,
+ "peak": 0.436492919921875,
+ "rms": 0.12388364970684052,
+ "qualityWarnings": []
+ },
+ "review": "not_listened",
+ "status": "draft",
+ "processing": "polyphase resample to mono PCM16 44100 Hz; no speech trimming"
+ },
+ {
+ "id": "count_07",
+ "sourceRunId": "20261004T161148012934Z_47f3a009",
+ "sourceFile": "generated/20261004T161148012934Z_47f3a009/count_07.wav",
+ "sourceSha256": "af505fe8825eda62af188ee9dfe79b1ee91ff819cbe8e07596af6f741e0bf5a4",
+ "editedFile": "edited/20261004T161231511126Z_aa20f404/count_07.wav",
+ "runtimeFile": "Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_07.wav",
+ "editedMetadata": {
+ "sha256": "7d4ba785ccb28b8f2bf0d8f66053dc8adf1a19d332bedfab3bffd596208fe829",
+ "sampleRate": 44100,
+ "channels": 1,
+ "frames": 24696,
+ "duration": 0.56,
+ "peak": 0.380279541015625,
+ "rms": 0.10288079082965851,
+ "qualityWarnings": []
+ },
+ "review": "not_listened",
+ "status": "draft",
+ "processing": "polyphase resample to mono PCM16 44100 Hz; no speech trimming"
+ },
+ {
+ "id": "count_08",
+ "sourceRunId": "20261004T161231511126Z_aa20f404",
+ "sourceFile": "generated/20261004T161231511126Z_aa20f404/count_08.wav",
+ "sourceSha256": "172ebad2a6e150a9c43088c78ec7f45040cfe13ea1c8b0515c6ec0fdf8020b23",
+ "editedFile": "edited/20261004T161231511126Z_aa20f404/count_08.wav",
+ "runtimeFile": "Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_08.wav",
+ "editedMetadata": {
+ "sha256": "6bde9265a8e4ac5a4209b1ddcebf57251430bd2eb5134a59af403f351a640aa2",
+ "sampleRate": 44100,
+ "channels": 1,
+ "frames": 63504,
+ "duration": 1.44,
+ "peak": 0.50177001953125,
+ "rms": 0.09600483626127243,
+ "qualityWarnings": []
+ },
+ "review": "not_listened",
+ "status": "draft",
+ "processing": "polyphase resample to mono PCM16 44100 Hz; no speech trimming"
+ },
+ {
+ "id": "count_09",
+ "sourceRunId": "20261004T161231511126Z_aa20f404",
+ "sourceFile": "generated/20261004T161231511126Z_aa20f404/count_09.wav",
+ "sourceSha256": "c4a0a9183e1a108a4f54b8364971de3693083e27f5f1f69d8bdba7030313cea5",
+ "editedFile": "edited/20261004T161231511126Z_aa20f404/count_09.wav",
+ "runtimeFile": "Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_09.wav",
+ "editedMetadata": {
+ "sha256": "4a921bc405ed5181e26365764ef94c2d311af45ed5508b27ffd7ac6d53d83802",
+ "sampleRate": 44100,
+ "channels": 1,
+ "frames": 28224,
+ "duration": 0.64,
+ "peak": 0.640716552734375,
+ "rms": 0.12261929363012314,
+ "qualityWarnings": []
+ },
+ "review": "not_listened",
+ "status": "draft",
+ "processing": "polyphase resample to mono PCM16 44100 Hz; no speech trimming"
+ },
+ {
+ "id": "count_10",
+ "sourceRunId": "20261004T161148012934Z_47f3a009",
+ "sourceFile": "generated/20261004T161148012934Z_47f3a009/count_10.wav",
+ "sourceSha256": "23e41b1b1ab51160979ac665301bbc91251505dedcf0c574f0f9fc5e457ac73a",
+ "editedFile": "edited/20261004T161231511126Z_aa20f404/count_10.wav",
+ "runtimeFile": "Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/count_10.wav",
+ "editedMetadata": {
+ "sha256": "b16ebccea20aedf93b884299edb0dd430f67e4deef069fb354b482f21b8e5fb8",
+ "sampleRate": 44100,
+ "channels": 1,
+ "frames": 28224,
+ "duration": 0.64,
+ "peak": 0.51031494140625,
+ "rms": 0.13129375874996185,
+ "qualityWarnings": []
+ },
+ "review": "not_listened",
+ "status": "draft",
+ "processing": "polyphase resample to mono PCM16 44100 Hz; no speech trimming"
+ },
+ {
+ "id": "guide_collect",
+ "sourceRunId": "20261004T161148012934Z_47f3a009",
+ "sourceFile": "generated/20261004T161148012934Z_47f3a009/guide_collect.wav",
+ "sourceSha256": "c772e4d9996b129eb4fdd59d90d03e93efa7ef434112e342be2e455d203878e6",
+ "editedFile": "edited/20261004T161231511126Z_aa20f404/guide_collect.wav",
+ "runtimeFile": "Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/guide_collect.wav",
+ "editedMetadata": {
+ "sha256": "62e15c9e38c36f4094a6c7e9c5148510141290b5f41db5aad9dc1d8f1a158594",
+ "sampleRate": 44100,
+ "channels": 1,
+ "frames": 88200,
+ "duration": 2.0,
+ "peak": 0.605316162109375,
+ "rms": 0.11202728003263474,
+ "qualityWarnings": []
+ },
+ "review": "not_listened",
+ "status": "draft",
+ "processing": "polyphase resample to mono PCM16 44100 Hz; no speech trimming"
+ },
+ {
+ "id": "guide_count",
+ "sourceRunId": "20261004T161231511126Z_aa20f404",
+ "sourceFile": "generated/20261004T161231511126Z_aa20f404/guide_count.wav",
+ "sourceSha256": "63086b0a17769a6c1a8e270f75db08db604b5eeb430456042e168ce95d02babe",
+ "editedFile": "edited/20261004T161231511126Z_aa20f404/guide_count.wav",
+ "runtimeFile": "Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/guide_count.wav",
+ "editedMetadata": {
+ "sha256": "debe29b89f3e2856f2bf4c5e01707a5f0a0657e5768c03be385ec88fa2328b40",
+ "sampleRate": 44100,
+ "channels": 1,
+ "frames": 158760,
+ "duration": 3.6,
+ "peak": 0.58233642578125,
+ "rms": 0.06778868287801743,
+ "qualityWarnings": []
+ },
+ "review": "not_listened",
+ "status": "draft",
+ "processing": "polyphase resample to mono PCM16 44100 Hz; no speech trimming"
+ }
+ ]
+}
diff --git a/SourceAssets/Audio/Voice/generated/20261004T161148012934Z_47f3a009/count_01.wav b/SourceAssets/Audio/Voice/generated/20261004T161148012934Z_47f3a009/count_01.wav
new file mode 100644
index 0000000..3d883c0
Binary files /dev/null and b/SourceAssets/Audio/Voice/generated/20261004T161148012934Z_47f3a009/count_01.wav differ
diff --git a/SourceAssets/Audio/Voice/generated/20261004T161148012934Z_47f3a009/count_04.wav b/SourceAssets/Audio/Voice/generated/20261004T161148012934Z_47f3a009/count_04.wav
new file mode 100644
index 0000000..5339b1f
Binary files /dev/null and b/SourceAssets/Audio/Voice/generated/20261004T161148012934Z_47f3a009/count_04.wav differ
diff --git a/SourceAssets/Audio/Voice/generated/20261004T161148012934Z_47f3a009/count_07.wav b/SourceAssets/Audio/Voice/generated/20261004T161148012934Z_47f3a009/count_07.wav
new file mode 100644
index 0000000..b128f91
Binary files /dev/null and b/SourceAssets/Audio/Voice/generated/20261004T161148012934Z_47f3a009/count_07.wav differ
diff --git a/SourceAssets/Audio/Voice/generated/20261004T161148012934Z_47f3a009/count_10.wav b/SourceAssets/Audio/Voice/generated/20261004T161148012934Z_47f3a009/count_10.wav
new file mode 100644
index 0000000..63a9a98
Binary files /dev/null and b/SourceAssets/Audio/Voice/generated/20261004T161148012934Z_47f3a009/count_10.wav differ
diff --git a/SourceAssets/Audio/Voice/generated/20261004T161148012934Z_47f3a009/guide_collect.wav b/SourceAssets/Audio/Voice/generated/20261004T161148012934Z_47f3a009/guide_collect.wav
new file mode 100644
index 0000000..948c1ba
Binary files /dev/null and b/SourceAssets/Audio/Voice/generated/20261004T161148012934Z_47f3a009/guide_collect.wav differ
diff --git a/SourceAssets/Audio/Voice/generated/20261004T161148012934Z_47f3a009/manifest.json b/SourceAssets/Audio/Voice/generated/20261004T161148012934Z_47f3a009/manifest.json
new file mode 100644
index 0000000..d04ee11
--- /dev/null
+++ b/SourceAssets/Audio/Voice/generated/20261004T161148012934Z_47f3a009/manifest.json
@@ -0,0 +1,149 @@
+{
+ "schemaVersion": 1,
+ "runId": "20261004T161148012934Z_47f3a009",
+ "createdUtc": "2026-10-04T16:11:48.013435+00:00",
+ "modelRevision": "0c0e3051f131929182e2c023b9537f8b1c68adfe",
+ "catalogHash": "491c9cd0bb7068a47b33bdd0b19ece1ba634217ec0ed9cc3e2c5aa7bd3802755",
+ "profileHash": "a5740d9db8a4aaebf08d0ac3b8f3225693f878aa2868143f01191a059e2680e8",
+ "scope": "selected",
+ "requestedIds": [
+ "count_01",
+ "count_04",
+ "count_07",
+ "count_10",
+ "guide_collect"
+ ],
+ "environment": {
+ "python": "3.12.15 | packaged by Anaconda, Inc. | (main, Oct 1 2026, 20:14:50) [MSC v.1942 64 bit (AMD64)]",
+ "packages": {
+ "qwen-tts": "0.1.1",
+ "torch": "2.11.0+cu128",
+ "torchaudio": "2.11.0",
+ "transformers": "4.57.3",
+ "soundfile": "0.14.0",
+ "huggingface-hub": "0.36.2"
+ },
+ "device": "NVIDIA GeForce RTX 4080 SUPER",
+ "cuda": "12.8",
+ "cudaProbe": 140.0,
+ "modelLoadSeconds": 3.2142242998816073,
+ "modelPeakVramBytes": 4181138432,
+ "modelDefaults": {
+ "do_sample": true,
+ "repetition_penalty": 1.05,
+ "temperature": 0.9,
+ "top_p": 1.0,
+ "top_k": 50,
+ "subtalker_dosample": true,
+ "subtalker_temperature": 0.9,
+ "subtalker_top_p": 1.0,
+ "subtalker_top_k": 50,
+ "max_new_tokens": 8192
+ },
+ "effectiveGenerationParameters": {
+ "do_sample": true,
+ "top_k": 50,
+ "top_p": 1,
+ "temperature": 0.9,
+ "repetition_penalty": 1.05,
+ "subtalker_dosample": true,
+ "subtalker_top_k": 50,
+ "subtalker_top_p": 1,
+ "subtalker_temperature": 0.9,
+ "max_new_tokens": 8192
+ },
+ "peakVramBytes": 4232247296
+ },
+ "clips": [
+ {
+ "id": "count_01",
+ "textHash": "4865b7d3cb44d273047c04c7f4ba1e2efdd2c489c365b9f5308f8e4c25c4ffe3",
+ "settingsHash": "a5740d9db8a4aaebf08d0ac3b8f3225693f878aa2868143f01191a059e2680e8",
+ "originalRunId": "20261004T161148012934Z_47f3a009",
+ "file": "generated/20261004T161148012934Z_47f3a009/count_01.wav",
+ "review": "not_listened",
+ "sha256": "cb7f5e25d8ba3e726b9557597002aef72c35e51edd6012defcb327728c10021f",
+ "sampleRate": 24000,
+ "channels": 1,
+ "frames": 13440,
+ "duration": 0.56,
+ "peak": 0.34375,
+ "rms": 0.07997916638851166,
+ "qualityWarnings": [],
+ "result": "generated",
+ "generationSeconds": 1.9430886001791805
+ },
+ {
+ "id": "count_04",
+ "textHash": "e59f364f775c0f9c35b6d10fe51b619e8ab96c11cf8da992bc06029e3d0f1d37",
+ "settingsHash": "a5740d9db8a4aaebf08d0ac3b8f3225693f878aa2868143f01191a059e2680e8",
+ "originalRunId": "20261004T161148012934Z_47f3a009",
+ "file": "generated/20261004T161148012934Z_47f3a009/count_04.wav",
+ "review": "not_listened",
+ "sha256": "c37c335baa80dbdade6e8c6163eb2339cda307d187258306e881b55ab7149f79",
+ "sampleRate": 24000,
+ "channels": 1,
+ "frames": 11520,
+ "duration": 0.48,
+ "peak": 0.3984375,
+ "rms": 0.07822784036397934,
+ "qualityWarnings": [],
+ "result": "generated",
+ "generationSeconds": 1.3012659000232816
+ },
+ {
+ "id": "count_07",
+ "textHash": "8708f4f2a79bf78f97f51d933a89dd25924309e39bc8ce863a18675d33aa6aae",
+ "settingsHash": "a5740d9db8a4aaebf08d0ac3b8f3225693f878aa2868143f01191a059e2680e8",
+ "originalRunId": "20261004T161148012934Z_47f3a009",
+ "file": "generated/20261004T161148012934Z_47f3a009/count_07.wav",
+ "review": "not_listened",
+ "sha256": "af505fe8825eda62af188ee9dfe79b1ee91ff819cbe8e07596af6f741e0bf5a4",
+ "sampleRate": 24000,
+ "channels": 1,
+ "frames": 13440,
+ "duration": 0.56,
+ "peak": 0.3671875,
+ "rms": 0.10282859951257706,
+ "qualityWarnings": [],
+ "result": "generated",
+ "generationSeconds": 1.304592999862507
+ },
+ {
+ "id": "count_10",
+ "textHash": "7502ee3bb6c7fcb6483d700bf145e8eee06b24db84f0eb90fb82dae84ce41f19",
+ "settingsHash": "a5740d9db8a4aaebf08d0ac3b8f3225693f878aa2868143f01191a059e2680e8",
+ "originalRunId": "20261004T161148012934Z_47f3a009",
+ "file": "generated/20261004T161148012934Z_47f3a009/count_10.wav",
+ "review": "not_listened",
+ "sha256": "23e41b1b1ab51160979ac665301bbc91251505dedcf0c574f0f9fc5e457ac73a",
+ "sampleRate": 24000,
+ "channels": 1,
+ "frames": 15360,
+ "duration": 0.64,
+ "peak": 0.5078125,
+ "rms": 0.1311955749988556,
+ "qualityWarnings": [],
+ "result": "generated",
+ "generationSeconds": 1.5336726000532508
+ },
+ {
+ "id": "guide_collect",
+ "textHash": "963c0253da8f4595da3ef968c576481f4590960d533b5059fcdfe8e791ee7a22",
+ "settingsHash": "a5740d9db8a4aaebf08d0ac3b8f3225693f878aa2868143f01191a059e2680e8",
+ "originalRunId": "20261004T161148012934Z_47f3a009",
+ "file": "generated/20261004T161148012934Z_47f3a009/guide_collect.wav",
+ "review": "not_listened",
+ "sha256": "c772e4d9996b129eb4fdd59d90d03e93efa7ef434112e342be2e455d203878e6",
+ "sampleRate": 24000,
+ "channels": 1,
+ "frames": 48000,
+ "duration": 2.0,
+ "peak": 0.60546875,
+ "rms": 0.11194184422492981,
+ "qualityWarnings": [],
+ "result": "generated",
+ "generationSeconds": 4.32505049998872
+ }
+ ]
+}
diff --git a/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/count_02.wav b/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/count_02.wav
new file mode 100644
index 0000000..9a66457
Binary files /dev/null and b/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/count_02.wav differ
diff --git a/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/count_03.wav b/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/count_03.wav
new file mode 100644
index 0000000..4a73e21
Binary files /dev/null and b/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/count_03.wav differ
diff --git a/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/count_05.wav b/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/count_05.wav
new file mode 100644
index 0000000..b41addc
Binary files /dev/null and b/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/count_05.wav differ
diff --git a/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/count_06.wav b/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/count_06.wav
new file mode 100644
index 0000000..2d3e987
Binary files /dev/null and b/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/count_06.wav differ
diff --git a/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/count_08.wav b/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/count_08.wav
new file mode 100644
index 0000000..a698828
Binary files /dev/null and b/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/count_08.wav differ
diff --git a/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/count_09.wav b/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/count_09.wav
new file mode 100644
index 0000000..bc05cc8
Binary files /dev/null and b/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/count_09.wav differ
diff --git a/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/guide_count.wav b/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/guide_count.wav
new file mode 100644
index 0000000..3b7f3c0
Binary files /dev/null and b/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/guide_count.wav differ
diff --git a/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/manifest.json b/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/manifest.json
new file mode 100644
index 0000000..a44d4d1
--- /dev/null
+++ b/SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/manifest.json
@@ -0,0 +1,282 @@
+{
+ "schemaVersion": 1,
+ "runId": "20261004T161231511126Z_aa20f404",
+ "createdUtc": "2026-10-04T16:12:31.511627+00:00",
+ "modelRevision": "0c0e3051f131929182e2c023b9537f8b1c68adfe",
+ "catalogHash": "491c9cd0bb7068a47b33bdd0b19ece1ba634217ec0ed9cc3e2c5aa7bd3802755",
+ "profileHash": "a5740d9db8a4aaebf08d0ac3b8f3225693f878aa2868143f01191a059e2680e8",
+ "scope": "all",
+ "requestedIds": [
+ "count_01",
+ "count_02",
+ "count_03",
+ "count_04",
+ "count_05",
+ "count_06",
+ "count_07",
+ "count_08",
+ "count_09",
+ "count_10",
+ "guide_collect",
+ "guide_count"
+ ],
+ "environment": {
+ "python": "3.12.15 | packaged by Anaconda, Inc. | (main, Oct 1 2026, 20:14:50) [MSC v.1942 64 bit (AMD64)]",
+ "packages": {
+ "qwen-tts": "0.1.1",
+ "torch": "2.11.0+cu128",
+ "torchaudio": "2.11.0",
+ "transformers": "4.57.3",
+ "soundfile": "0.14.0",
+ "huggingface-hub": "0.36.2"
+ },
+ "device": "NVIDIA GeForce RTX 4080 SUPER",
+ "cuda": "12.8",
+ "cudaProbe": 140.0,
+ "modelLoadSeconds": 3.5885288000572473,
+ "modelPeakVramBytes": 4181138432,
+ "modelDefaults": {
+ "do_sample": true,
+ "repetition_penalty": 1.05,
+ "temperature": 0.9,
+ "top_p": 1.0,
+ "top_k": 50,
+ "subtalker_dosample": true,
+ "subtalker_temperature": 0.9,
+ "subtalker_top_p": 1.0,
+ "subtalker_top_k": 50,
+ "max_new_tokens": 8192
+ },
+ "effectiveGenerationParameters": {
+ "do_sample": true,
+ "top_k": 50,
+ "top_p": 1,
+ "temperature": 0.9,
+ "repetition_penalty": 1.05,
+ "subtalker_dosample": true,
+ "subtalker_top_k": 50,
+ "subtalker_top_p": 1,
+ "subtalker_temperature": 0.9,
+ "max_new_tokens": 8192
+ },
+ "peakVramBytes": 4386499584
+ },
+ "clips": [
+ {
+ "id": "count_01",
+ "textHash": "4865b7d3cb44d273047c04c7f4ba1e2efdd2c489c365b9f5308f8e4c25c4ffe3",
+ "settingsHash": "a5740d9db8a4aaebf08d0ac3b8f3225693f878aa2868143f01191a059e2680e8",
+ "originalRunId": "20261004T161148012934Z_47f3a009",
+ "file": "generated/20261004T161148012934Z_47f3a009/count_01.wav",
+ "review": "not_listened",
+ "sha256": "cb7f5e25d8ba3e726b9557597002aef72c35e51edd6012defcb327728c10021f",
+ "sampleRate": 24000,
+ "channels": 1,
+ "frames": 13440,
+ "duration": 0.56,
+ "peak": 0.34375,
+ "rms": 0.07997916638851166,
+ "qualityWarnings": [],
+ "result": "reused",
+ "generationSeconds": 1.9430886001791805
+ },
+ {
+ "id": "count_02",
+ "textHash": "54f6f26d54a9f881dc98fed4b08248d2f00544f85a6c9ef231594d8389eadd1b",
+ "settingsHash": "a5740d9db8a4aaebf08d0ac3b8f3225693f878aa2868143f01191a059e2680e8",
+ "originalRunId": "20261004T161231511126Z_aa20f404",
+ "file": "generated/20261004T161231511126Z_aa20f404/count_02.wav",
+ "review": "not_listened",
+ "sha256": "ee8b600198b802248715beafe51848066ce4955c20ac600d5b577590372830cf",
+ "sampleRate": 24000,
+ "channels": 1,
+ "frames": 24960,
+ "duration": 1.04,
+ "peak": 0.478515625,
+ "rms": 0.09962195158004761,
+ "qualityWarnings": [],
+ "result": "generated",
+ "generationSeconds": 3.058615499874577
+ },
+ {
+ "id": "count_03",
+ "textHash": "d79e344ee129a74f8a4212c256a5b80f071b1a8dbbeeded084e3e4ff046e6b9d",
+ "settingsHash": "a5740d9db8a4aaebf08d0ac3b8f3225693f878aa2868143f01191a059e2680e8",
+ "originalRunId": "20261004T161231511126Z_aa20f404",
+ "file": "generated/20261004T161231511126Z_aa20f404/count_03.wav",
+ "review": "not_listened",
+ "sha256": "572416e0d66821e1b939833cab328c23b5c97aef2233619428cd54c0603b6b12",
+ "sampleRate": 24000,
+ "channels": 1,
+ "frames": 11520,
+ "duration": 0.48,
+ "peak": 0.87109375,
+ "rms": 0.16225309669971466,
+ "qualityWarnings": [],
+ "result": "generated",
+ "generationSeconds": 1.1792403999716043
+ },
+ {
+ "id": "count_04",
+ "textHash": "e59f364f775c0f9c35b6d10fe51b619e8ab96c11cf8da992bc06029e3d0f1d37",
+ "settingsHash": "a5740d9db8a4aaebf08d0ac3b8f3225693f878aa2868143f01191a059e2680e8",
+ "originalRunId": "20261004T161148012934Z_47f3a009",
+ "file": "generated/20261004T161148012934Z_47f3a009/count_04.wav",
+ "review": "not_listened",
+ "sha256": "c37c335baa80dbdade6e8c6163eb2339cda307d187258306e881b55ab7149f79",
+ "sampleRate": 24000,
+ "channels": 1,
+ "frames": 11520,
+ "duration": 0.48,
+ "peak": 0.3984375,
+ "rms": 0.07822784036397934,
+ "qualityWarnings": [],
+ "result": "reused",
+ "generationSeconds": 1.3012659000232816
+ },
+ {
+ "id": "count_05",
+ "textHash": "85662c79a7da0157be376388613950f14efd961d11dc4918f7ceb3f8b5a87c6d",
+ "settingsHash": "a5740d9db8a4aaebf08d0ac3b8f3225693f878aa2868143f01191a059e2680e8",
+ "originalRunId": "20261004T161231511126Z_aa20f404",
+ "file": "generated/20261004T161231511126Z_aa20f404/count_05.wav",
+ "review": "not_listened",
+ "sha256": "8b0c3a36c6608834783a6781d1ff4c2aabc81e4a4ccf841e19f1729087cfc3e5",
+ "sampleRate": 24000,
+ "channels": 1,
+ "frames": 218880,
+ "duration": 9.12,
+ "peak": 0.443359375,
+ "rms": 0.035190436989068985,
+ "qualityWarnings": [],
+ "result": "generated",
+ "generationSeconds": 21.367234900128096
+ },
+ {
+ "id": "count_06",
+ "textHash": "cdb3d4e6e62355db4248cab7b1c1ffb6a3b381d16534c7bdab2b66d4f655688b",
+ "settingsHash": "a5740d9db8a4aaebf08d0ac3b8f3225693f878aa2868143f01191a059e2680e8",
+ "originalRunId": "20261004T161231511126Z_aa20f404",
+ "file": "generated/20261004T161231511126Z_aa20f404/count_06.wav",
+ "review": "not_listened",
+ "sha256": "235c4b6a73be845080af4a10508c433e3d6bf05cb4e0445cba18e23e367d51f7",
+ "sampleRate": 24000,
+ "channels": 1,
+ "frames": 24960,
+ "duration": 1.04,
+ "peak": 0.435546875,
+ "rms": 0.123788021504879,
+ "qualityWarnings": [],
+ "result": "generated",
+ "generationSeconds": 2.4236581998411566
+ },
+ {
+ "id": "count_07",
+ "textHash": "8708f4f2a79bf78f97f51d933a89dd25924309e39bc8ce863a18675d33aa6aae",
+ "settingsHash": "a5740d9db8a4aaebf08d0ac3b8f3225693f878aa2868143f01191a059e2680e8",
+ "originalRunId": "20261004T161148012934Z_47f3a009",
+ "file": "generated/20261004T161148012934Z_47f3a009/count_07.wav",
+ "review": "not_listened",
+ "sha256": "af505fe8825eda62af188ee9dfe79b1ee91ff819cbe8e07596af6f741e0bf5a4",
+ "sampleRate": 24000,
+ "channels": 1,
+ "frames": 13440,
+ "duration": 0.56,
+ "peak": 0.3671875,
+ "rms": 0.10282859951257706,
+ "qualityWarnings": [],
+ "result": "reused",
+ "generationSeconds": 1.304592999862507
+ },
+ {
+ "id": "count_08",
+ "textHash": "0d69107ef88a2330a9ae98f541307c80491ec2e0d2cbaa085d0b2ccdb4ab8a0b",
+ "settingsHash": "a5740d9db8a4aaebf08d0ac3b8f3225693f878aa2868143f01191a059e2680e8",
+ "originalRunId": "20261004T161231511126Z_aa20f404",
+ "file": "generated/20261004T161231511126Z_aa20f404/count_08.wav",
+ "review": "not_listened",
+ "sha256": "172ebad2a6e150a9c43088c78ec7f45040cfe13ea1c8b0515c6ec0fdf8020b23",
+ "sampleRate": 24000,
+ "channels": 1,
+ "frames": 34560,
+ "duration": 1.44,
+ "peak": 0.5,
+ "rms": 0.09592147916555405,
+ "qualityWarnings": [],
+ "result": "generated",
+ "generationSeconds": 3.9671265999786556
+ },
+ {
+ "id": "count_09",
+ "textHash": "e9c0b4b5874aa37dc2587999c6e6c82437f6a9a9f9f6478b86cc89b1c585c941",
+ "settingsHash": "a5740d9db8a4aaebf08d0ac3b8f3225693f878aa2868143f01191a059e2680e8",
+ "originalRunId": "20261004T161231511126Z_aa20f404",
+ "file": "generated/20261004T161231511126Z_aa20f404/count_09.wav",
+ "review": "not_listened",
+ "sha256": "c4a0a9183e1a108a4f54b8364971de3693083e27f5f1f69d8bdba7030313cea5",
+ "sampleRate": 24000,
+ "channels": 1,
+ "frames": 15360,
+ "duration": 0.64,
+ "peak": 0.640625,
+ "rms": 0.12247619032859802,
+ "qualityWarnings": [],
+ "result": "generated",
+ "generationSeconds": 1.9335036999545991
+ },
+ {
+ "id": "count_10",
+ "textHash": "7502ee3bb6c7fcb6483d700bf145e8eee06b24db84f0eb90fb82dae84ce41f19",
+ "settingsHash": "a5740d9db8a4aaebf08d0ac3b8f3225693f878aa2868143f01191a059e2680e8",
+ "originalRunId": "20261004T161148012934Z_47f3a009",
+ "file": "generated/20261004T161148012934Z_47f3a009/count_10.wav",
+ "review": "not_listened",
+ "sha256": "23e41b1b1ab51160979ac665301bbc91251505dedcf0c574f0f9fc5e457ac73a",
+ "sampleRate": 24000,
+ "channels": 1,
+ "frames": 15360,
+ "duration": 0.64,
+ "peak": 0.5078125,
+ "rms": 0.1311955749988556,
+ "qualityWarnings": [],
+ "result": "reused",
+ "generationSeconds": 1.5336726000532508
+ },
+ {
+ "id": "guide_collect",
+ "textHash": "963c0253da8f4595da3ef968c576481f4590960d533b5059fcdfe8e791ee7a22",
+ "settingsHash": "a5740d9db8a4aaebf08d0ac3b8f3225693f878aa2868143f01191a059e2680e8",
+ "originalRunId": "20261004T161148012934Z_47f3a009",
+ "file": "generated/20261004T161148012934Z_47f3a009/guide_collect.wav",
+ "review": "not_listened",
+ "sha256": "c772e4d9996b129eb4fdd59d90d03e93efa7ef434112e342be2e455d203878e6",
+ "sampleRate": 24000,
+ "channels": 1,
+ "frames": 48000,
+ "duration": 2.0,
+ "peak": 0.60546875,
+ "rms": 0.11194184422492981,
+ "qualityWarnings": [],
+ "result": "reused",
+ "generationSeconds": 4.32505049998872
+ },
+ {
+ "id": "guide_count",
+ "textHash": "b1dc061607df3f064c4e2625adaf2579dabd9b15ef68bda16a3583035838e1a2",
+ "settingsHash": "a5740d9db8a4aaebf08d0ac3b8f3225693f878aa2868143f01191a059e2680e8",
+ "originalRunId": "20261004T161231511126Z_aa20f404",
+ "file": "generated/20261004T161231511126Z_aa20f404/guide_count.wav",
+ "review": "not_listened",
+ "sha256": "63086b0a17769a6c1a8e270f75db08db604b5eeb430456042e168ce95d02babe",
+ "sampleRate": 24000,
+ "channels": 1,
+ "frames": 86400,
+ "duration": 3.6,
+ "peak": 0.578125,
+ "rms": 0.06774810701608658,
+ "qualityWarnings": [],
+ "result": "generated",
+ "generationSeconds": 8.88178739999421
+ }
+ ]
+}
diff --git a/SourceAssets/Audio/Voice/licenses/Qwen3-TTS-code-Apache-2.0.txt b/SourceAssets/Audio/Voice/licenses/Qwen3-TTS-code-Apache-2.0.txt
new file mode 100644
index 0000000..c347eb5
--- /dev/null
+++ b/SourceAssets/Audio/Voice/licenses/Qwen3-TTS-code-Apache-2.0.txt
@@ -0,0 +1,201 @@
+ Apache License
+ Version 2.0, January 2004
+ http://www.apache.org/licenses/
+
+ TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
+
+ 1. Definitions.
+
+ "License" shall mean the terms and conditions for use, reproduction,
+ and distribution as defined by Sections 1 through 9 of this document.
+
+ "Licensor" shall mean the copyright owner or entity authorized by
+ the copyright owner that is granting the License.
+
+ "Legal Entity" shall mean the union of the acting entity and all
+ other entities that control, are controlled by, or are under common
+ control with that entity. For the purposes of this definition,
+ "control" means (i) the power, direct or indirect, to cause the
+ direction or management of such entity, whether by contract or
+ otherwise, or (ii) ownership of fifty percent (50%) or more of the
+ outstanding shares, or (iii) beneficial ownership of such entity.
+
+ "You" (or "Your") shall mean an individual or Legal Entity
+ exercising permissions granted by this License.
+
+ "Source" form shall mean the preferred form for making modifications,
+ including but not limited to software source code, documentation
+ source, and configuration files.
+
+ "Object" form shall mean any form resulting from mechanical
+ transformation or translation of a Source form, including but
+ not limited to compiled object code, generated documentation,
+ and conversions to other media types.
+
+ "Work" shall mean the work of authorship, whether in Source or
+ Object form, made available under the License, as indicated by a
+ copyright notice that is included in or attached to the work
+ (an example is provided in the Appendix below).
+
+ "Derivative Works" shall mean any work, whether in Source or Object
+ form, that is based on (or derived from) the Work and for which the
+ editorial revisions, annotations, elaborations, or other modifications
+ represent, as a whole, an original work of authorship. For the purposes
+ of this License, Derivative Works shall not include works that remain
+ separable from, or merely link (or bind by name) to the interfaces of,
+ the Work and Derivative Works thereof.
+
+ "Contribution" shall mean any work of authorship, including
+ the original version of the Work and any modifications or additions
+ to that Work or Derivative Works thereof, that is intentionally
+ submitted to Licensor for inclusion in the Work by the copyright owner
+ or by an individual or Legal Entity authorized to submit on behalf of
+ the copyright owner. For the purposes of this definition, "submitted"
+ means any form of electronic, verbal, or written communication sent
+ to the Licensor or its representatives, including but not limited to
+ communication on electronic mailing lists, source code control systems,
+ and issue tracking systems that are managed by, or on behalf of, the
+ Licensor for the purpose of discussing and improving the Work, but
+ excluding communication that is conspicuously marked or otherwise
+ designated in writing by the copyright owner as "Not a Contribution."
+
+ "Contributor" shall mean Licensor and any individual or Legal Entity
+ on behalf of whom a Contribution has been received by Licensor and
+ subsequently incorporated within the Work.
+
+ 2. Grant of Copyright License. Subject to the terms and conditions of
+ this License, each Contributor hereby grants to You a perpetual,
+ worldwide, non-exclusive, no-charge, royalty-free, irrevocable
+ copyright license to reproduce, prepare Derivative Works of,
+ publicly display, publicly perform, sublicense, and distribute the
+ Work and such Derivative Works in Source or Object form.
+
+ 3. Grant of Patent License. Subject to the terms and conditions of
+ this License, each Contributor hereby grants to You a perpetual,
+ worldwide, non-exclusive, no-charge, royalty-free, irrevocable
+ (except as stated in this section) patent license to make, have made,
+ use, offer to sell, sell, import, and otherwise transfer the Work,
+ where such license applies only to those patent claims licensable
+ by such Contributor that are necessarily infringed by their
+ Contribution(s) alone or by combination of their Contribution(s)
+ with the Work to which such Contribution(s) was submitted. If You
+ institute patent litigation against any entity (including a
+ cross-claim or counterclaim in a lawsuit) alleging that the Work
+ or a Contribution incorporated within the Work constitutes direct
+ or contributory patent infringement, then any patent licenses
+ granted to You under this License for that Work shall terminate
+ as of the date such litigation is filed.
+
+ 4. Redistribution. You may reproduce and distribute copies of the
+ Work or Derivative Works thereof in any medium, with or without
+ modifications, and in Source or Object form, provided that You
+ meet the following conditions:
+
+ (a) You must give any other recipients of the Work or
+ Derivative Works a copy of this License; and
+
+ (b) You must cause any modified files to carry prominent notices
+ stating that You changed the files; and
+
+ (c) You must retain, in the Source form of any Derivative Works
+ that You distribute, all copyright, patent, trademark, and
+ attribution notices from the Source form of the Work,
+ excluding those notices that do not pertain to any part of
+ the Derivative Works; and
+
+ (d) If the Work includes a "NOTICE" text file as part of its
+ distribution, then any Derivative Works that You distribute must
+ include a readable copy of the attribution notices contained
+ within such NOTICE file, excluding those notices that do not
+ pertain to any part of the Derivative Works, in at least one
+ of the following places: within a NOTICE text file distributed
+ as part of the Derivative Works; within the Source form or
+ documentation, if provided along with the Derivative Works; or,
+ within a display generated by the Derivative Works, if and
+ wherever such third-party notices normally appear. The contents
+ of the NOTICE file are for informational purposes only and
+ do not modify the License. You may add Your own attribution
+ notices within Derivative Works that You distribute, alongside
+ or as an addendum to the NOTICE text from the Work, provided
+ that such additional attribution notices cannot be construed
+ as modifying the License.
+
+ You may add Your own copyright statement to Your modifications and
+ may provide additional or different license terms and conditions
+ for use, reproduction, or distribution of Your modifications, or
+ for any such Derivative Works as a whole, provided Your use,
+ reproduction, and distribution of the Work otherwise complies with
+ the conditions stated in this License.
+
+ 5. Submission of Contributions. Unless You explicitly state otherwise,
+ any Contribution intentionally submitted for inclusion in the Work
+ by You to the Licensor shall be under the terms and conditions of
+ this License, without any additional terms or conditions.
+ Notwithstanding the above, nothing herein shall supersede or modify
+ the terms of any separate license agreement you may have executed
+ with Licensor regarding such Contributions.
+
+ 6. Trademarks. This License does not grant permission to use the trade
+ names, trademarks, service marks, or product names of the Licensor,
+ except as required for reasonable and customary use in describing the
+ origin of the Work and reproducing the content of the NOTICE file.
+
+ 7. Disclaimer of Warranty. Unless required by applicable law or
+ agreed to in writing, Licensor provides the Work (and each
+ Contributor provides its Contributions) on an "AS IS" BASIS,
+ WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
+ implied, including, without limitation, any warranties or conditions
+ of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
+ PARTICULAR PURPOSE. You are solely responsible for determining the
+ appropriateness of using or redistributing the Work and assume any
+ risks associated with Your exercise of permissions under this License.
+
+ 8. Limitation of Liability. In no event and under no legal theory,
+ whether in tort (including negligence), contract, or otherwise,
+ unless required by applicable law (such as deliberate and grossly
+ negligent acts) or agreed to in writing, shall any Contributor be
+ liable to You for damages, including any direct, indirect, special,
+ incidental, or consequential damages of any character arising as a
+ result of this License or out of the use or inability to use the
+ Work (including but not limited to damages for loss of goodwill,
+ work stoppage, computer failure or malfunction, or any and all
+ other commercial damages or losses), even if such Contributor
+ has been advised of the possibility of such damages.
+
+ 9. Accepting Warranty or Additional Liability. While redistributing
+ the Work or Derivative Works thereof, You may choose to offer,
+ and charge a fee for, acceptance of support, warranty, indemnity,
+ or other liability obligations and/or rights consistent with this
+ License. However, in accepting such obligations, You may act only
+ on Your own behalf and on Your sole responsibility, not on behalf
+ of any other Contributor, and only if You agree to indemnify,
+ defend, and hold each Contributor harmless for any liability
+ incurred by, or claims asserted against, such Contributor by reason
+ of your accepting any such warranty or additional liability.
+
+ END OF TERMS AND CONDITIONS
+
+ APPENDIX: How to apply the Apache License to your work.
+
+ To apply the Apache License to your work, attach the following
+ boilerplate notice, with the fields enclosed by brackets "[]"
+ replaced with your own identifying information. (Don't include
+ the brackets!) The text should be enclosed in the appropriate
+ comment syntax for the file format. We also recommend that a
+ file or class name and description of purpose be included on the
+ same "printed page" as the copyright notice for easier
+ identification within third-party archives.
+
+ Copyright 2026 Alibaba Cloud
+
+ Licensed under the Apache License, Version 2.0 (the "License");
+ you may not use this file except in compliance with the License.
+ You may obtain a copy of the License at
+
+ http://www.apache.org/licenses/LICENSE-2.0
+
+ Unless required by applicable law or agreed to in writing, software
+ distributed under the License is distributed on an "AS IS" BASIS,
+ WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+ See the License for the specific language governing permissions and
+ limitations under the License.
diff --git a/SourceAssets/Audio/Voice/licenses/model-card-0c0e3051.md b/SourceAssets/Audio/Voice/licenses/model-card-0c0e3051.md
new file mode 100644
index 0000000..7fbce7d
--- /dev/null
+++ b/SourceAssets/Audio/Voice/licenses/model-card-0c0e3051.md
@@ -0,0 +1,1316 @@
+---
+license: apache-2.0
+pipeline_tag: text-to-speech
+---
+
+# Qwen3-TTS
+
+## Overview
+### Introduction
+
+
+  +
+
+Qwen3-TTS covers 10 major languages (Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, and Italian) as well as multiple dialectal voice profiles to meet global application needs. In addition, the models feature strong contextual understanding, enabling adaptive control of tone, speaking rate, and emotional expression based on instructions and text semantics, and they show markedly improved robustness to noisy input text. Key features:
+
+* **Powerful Speech Representation**: Powered by the self-developed Qwen3-TTS-Tokenizer-12Hz, it achieves efficient acoustic compression and high-dimensional semantic modeling of speech signals. It fully preserves paralinguistic information and acoustic environmental features, enabling high-speed, high-fidelity speech reconstruction through a lightweight non-DiT architecture.
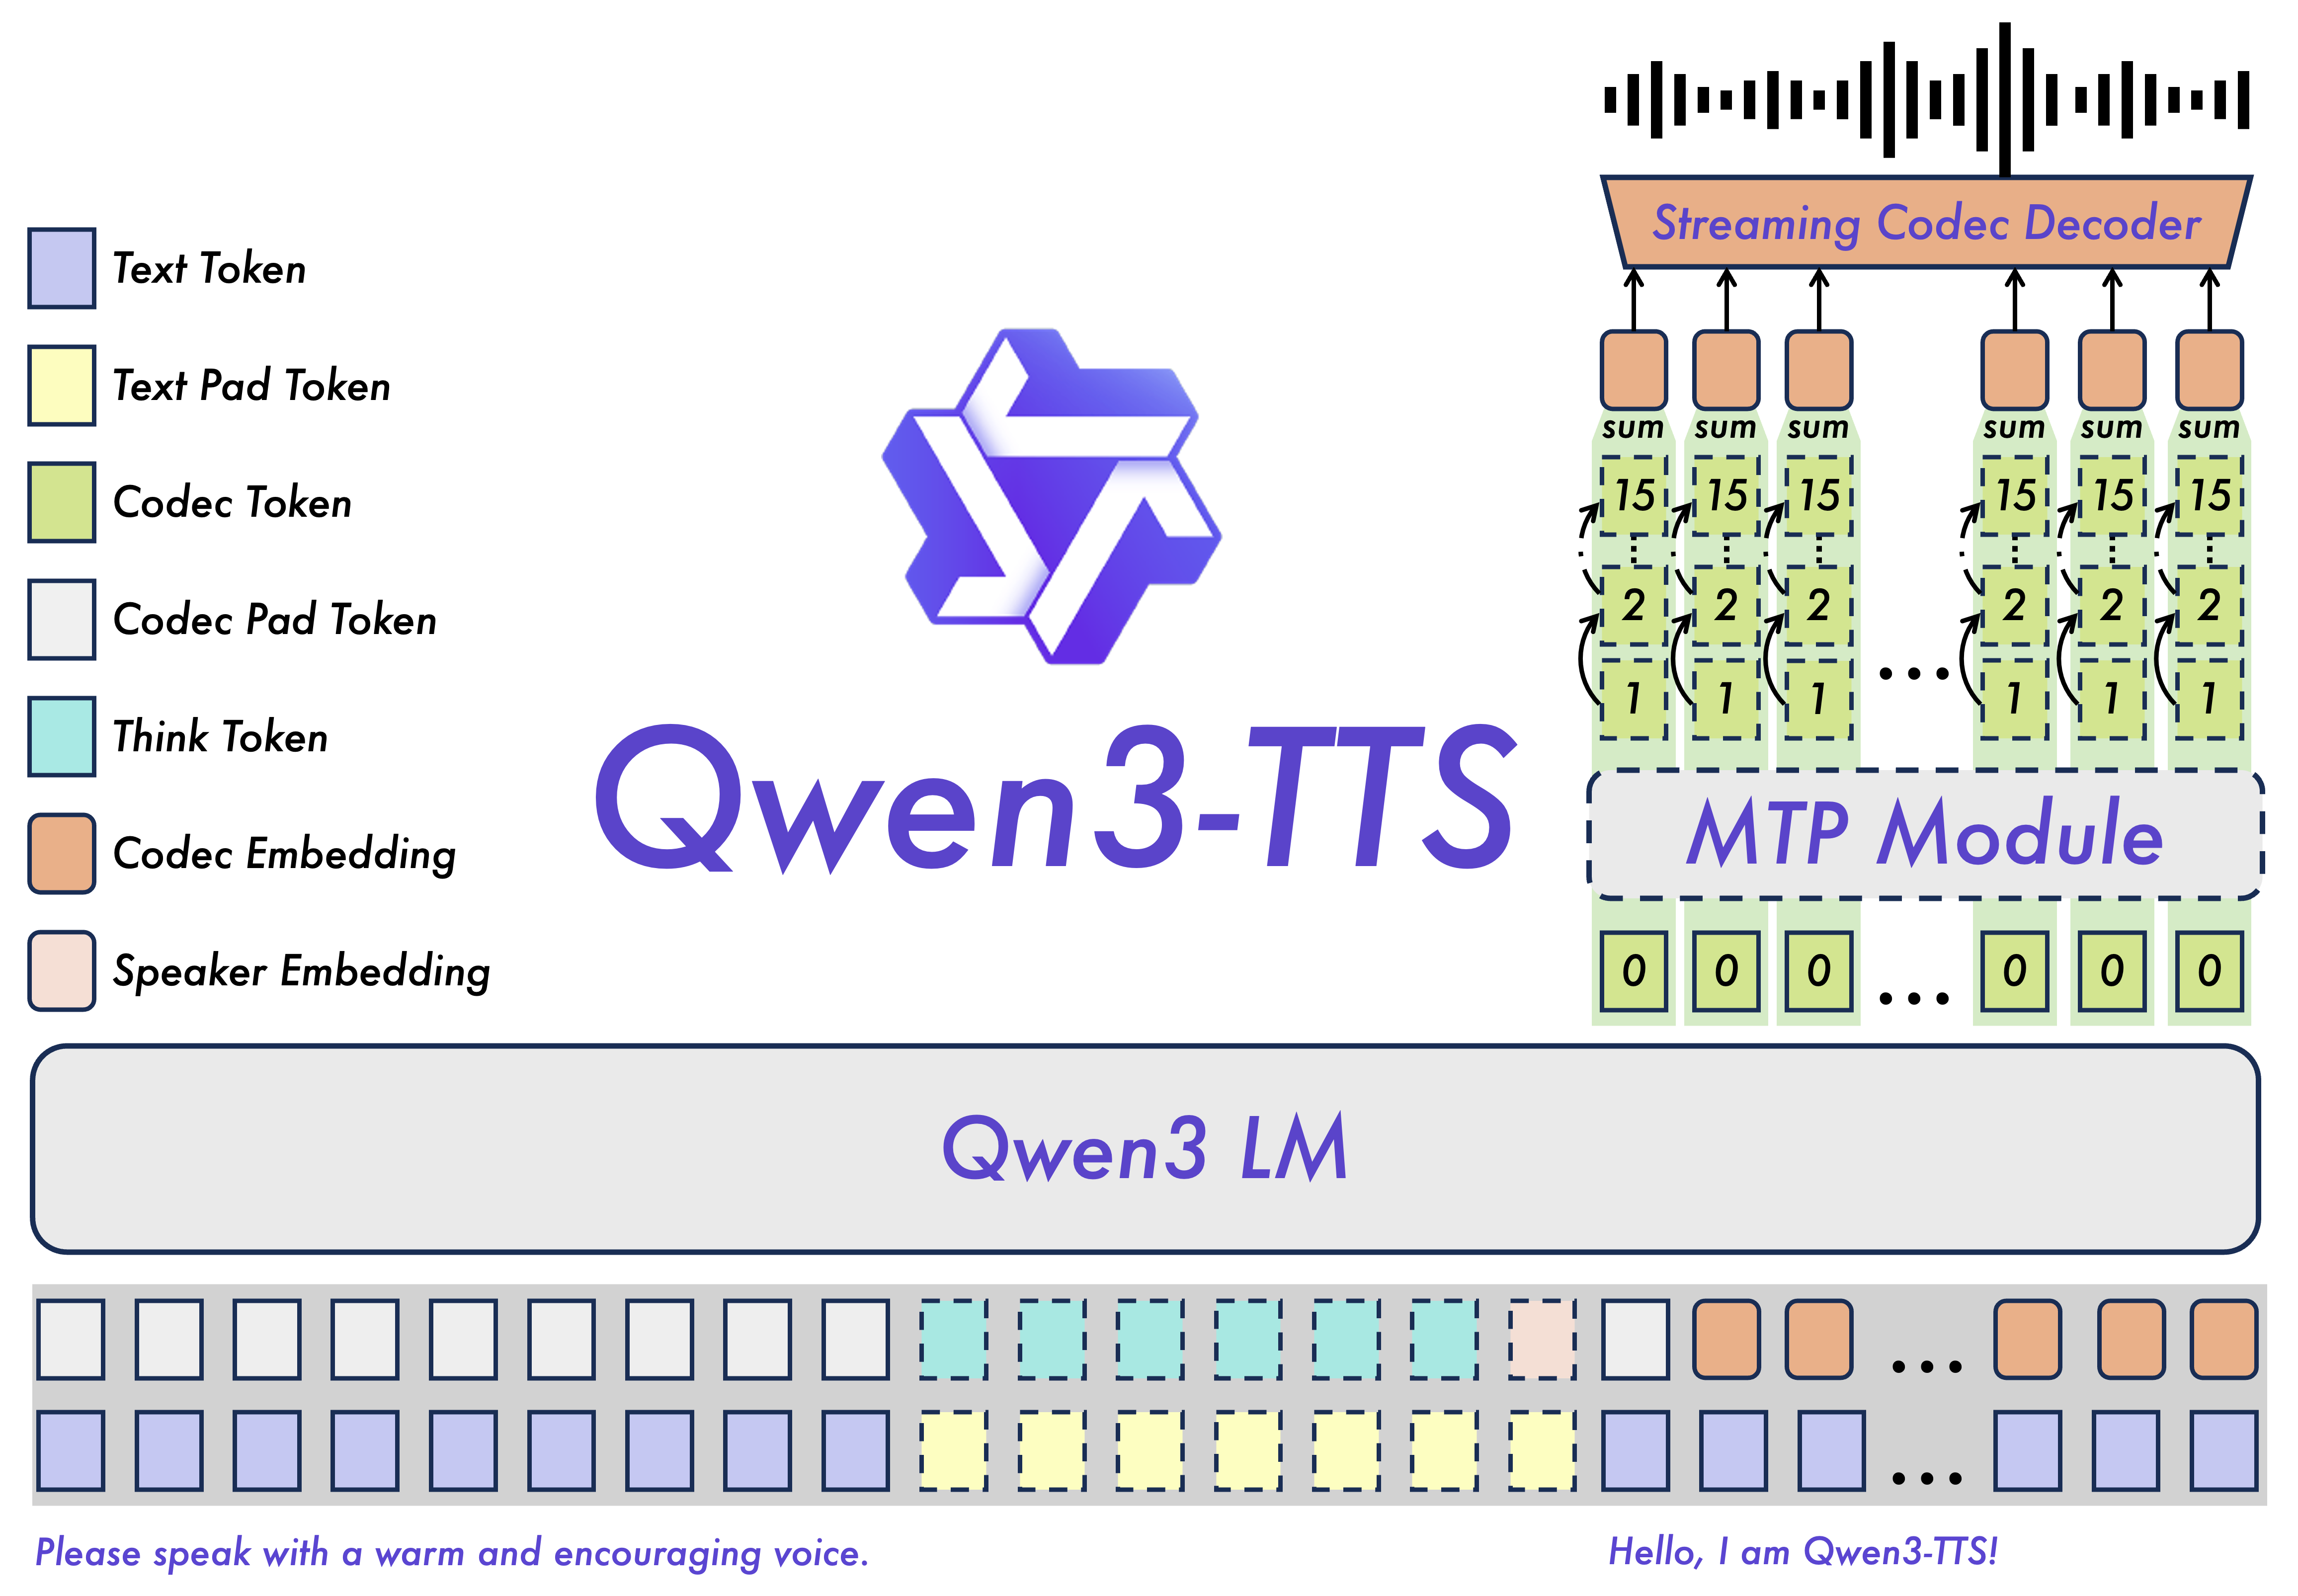
+* **Universal End-to-End Architecture**: Utilizing a discrete multi-codebook LM architecture, it realizes full-information end-to-end speech modeling. This completely bypasses the information bottlenecks and cascading errors inherent in traditional LM+DiT schemes, significantly enhancing the model’s versatility, generation efficiency, and performance ceiling.
+* **Extreme Low-Latency Streaming Generation**: Based on the innovative Dual-Track hybrid streaming generation architecture, a single model supports both streaming and non-streaming generation. It can output the first audio packet immediately after a single character is input, with end-to-end synthesis latency as low as 97ms, meeting the rigorous demands of real-time interactive scenarios.
+* **Intelligent Text Understanding and Voice Control**: Supports speech generation driven by natural language instructions, allowing for flexible control over multi-dimensional acoustic attributes such as timbre, emotion, and prosody. By deeply integrating text semantic understanding, the model adaptively adjusts tone, rhythm, and emotional expression, achieving lifelike “what you imagine is what you hear” output.
+
+
+### Model Architecture
+
+
+  +
+
+### Released Models Description and Download
+
+Below is an introduction and download information for the Qwen3-TTS models that have already been released. Other models mentioned in the technical report will be released in the near future. Please select and download the model that fits your needs.
+
+| Tokenizer Name | Description |
+|---------------------------------|-------------|
+| Qwen3-TTS-Tokenizer-12Hz | The Qwen3-TTS-Tokenizer-12Hz model which can encode the input speech into codes and decode them back into speech. |
+
+
+| Model | Features | Language Support | Streaming | Instruction Control |
+|---|---|---|---|---|
+| Qwen3-TTS-12Hz-1.7B-VoiceDesign | Performs voice design based on user-provided descriptions. | Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, Italian | ✅ | ✅ |
+| Qwen3-TTS-12Hz-1.7B-CustomVoice | Provides style control over target timbres via user instructions; supports 9 premium timbres covering various combinations of gender, age, language, and dialect. | Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, Italian | ✅ | ✅ |
+| Qwen3-TTS-12Hz-1.7B-Base | Base model capable of 3-second rapid voice clone from user audio input; can be used for fine-tuning (FT) other models. | Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, Italian | ✅ | |
+| Qwen3-TTS-12Hz-0.6B-CustomVoice | Supports 9 premium timbres covering various combinations of gender, age, language, and dialect. | Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, Italian | ✅ | |
+| Qwen3-TTS-12Hz-0.6B-Base | Base model capable of 3-second rapid voice clone from user audio input; can be used for fine-tuning (FT) other models. | Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, Italian | ✅ | |
+
+During model loading in the qwen-tts package or vLLM, model weights will be automatically downloaded based on the model name. However, if your runtime environment is not conducive to downloading weights during execution, you can refer to the following commands to manually download the model weights to a local directory:
+
+```bash
+# Download through ModelScope (recommended for users in Mainland China)
+pip install -U modelscope
+modelscope download --model Qwen/Qwen3-TTS-Tokenizer-12Hz --local_dir ./Qwen3-TTS-Tokenizer-12Hz
+modelscope download --model Qwen/Qwen3-TTS-12Hz-1.7B-CustomVoice --local_dir ./Qwen3-TTS-12Hz-1.7B-CustomVoice
+modelscope download --model Qwen/Qwen3-TTS-12Hz-1.7B-VoiceDesign --local_dir ./Qwen3-TTS-12Hz-1.7B-VoiceDesign
+modelscope download --model Qwen/Qwen3-TTS-12Hz-1.7B-Base --local_dir ./Qwen3-TTS-12Hz-1.7B-Base
+modelscope download --model Qwen/Qwen3-TTS-12Hz-0.6B-CustomVoice --local_dir ./Qwen3-TTS-12Hz-0.6B-CustomVoice
+modelscope download --model Qwen/Qwen3-TTS-12Hz-0.6B-Base --local_dir ./Qwen3-TTS-12Hz-0.6B-Base
+
+# Download through Hugging Face
+pip install -U "huggingface_hub[cli]"
+huggingface-cli download Qwen/Qwen3-TTS-Tokenizer-12Hz --local-dir ./Qwen3-TTS-Tokenizer-12Hz
+huggingface-cli download Qwen/Qwen3-TTS-12Hz-1.7B-CustomVoice --local-dir ./Qwen3-TTS-12Hz-1.7B-CustomVoice
+huggingface-cli download Qwen/Qwen3-TTS-12Hz-1.7B-VoiceDesign --local-dir ./Qwen3-TTS-12Hz-1.7B-VoiceDesign
+huggingface-cli download Qwen/Qwen3-TTS-12Hz-1.7B-Base --local-dir ./Qwen3-TTS-12Hz-1.7B-Base
+huggingface-cli download Qwen/Qwen3-TTS-12Hz-0.6B-CustomVoice --local-dir ./Qwen3-TTS-12Hz-0.6B-CustomVoice
+huggingface-cli download Qwen/Qwen3-TTS-12Hz-0.6B-Base --local-dir ./Qwen3-TTS-12Hz-0.6B-Base
+```
+
+
+## Quickstart
+
+### Environment Setup
+
+The easiest way to quickly use Qwen3-TTS is to install the `qwen-tts` Python package from PyPI. This will pull in the required runtime dependencies and allow you to load any released Qwen3-TTS model. We recommend using a **fresh, isolated environment** to avoid dependency conflicts with existing packages. You can create a clean Python 3.12 environment like this:
+
+```bash
+conda create -n qwen3-tts python=3.12 -y
+conda activate qwen3-tts
+```
+
+then run:
+
+```bash
+pip install -U qwen-tts
+```
+
+If you want to develop or modify the code locally, install from source in editable mode.
+
+```bash
+git clone https://github.com/QwenLM/Qwen3-TTS.git
+cd Qwen3-TTS
+pip install -e .
+```
+
+Additionally, we recommend using FlashAttention 2 to reduce GPU memory usage.
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+If your machine has less than 96GB of RAM and lots of CPU cores, run:
+
+```bash
+MAX_JOBS=4 pip install -U flash-attn --no-build-isolation
+```
+
+Also, you should have hardware that is compatible with FlashAttention 2. Read more about it in the official documentation of the [FlashAttention repository](https://github.com/Dao-AILab/flash-attention). FlashAttention 2 can only be used when a model is loaded in `torch.float16` or `torch.bfloat16`.
+
+
+### Python Package Usage
+
+After installation, you can import `Qwen3TTSModel` to run custom voice TTS, voice design, and voice clone. The model weights can be specified either as a Hugging Face model id (recommended) or as a local directory path you downloaded. For all the `generate_*` functions below, besides the parameters shown and explicitly documented, you can also pass generation kwargs supported by Hugging Face Transformers `model.generate`, e.g., `max_new_tokens`, `top_p`, etc.
+
+#### Custom Voice Generate
+
+For custom voice models (`Qwen3-TTS-12Hz-1.7B/0.6B-CustomVoice`), you just need to call `generate_custom_voice`, passing a single string or a batch list, along with `language`, `speaker`, and optional `instruct`. You can also call `model.get_supported_speakers()` and `model.get_supported_languages()` to see which speakers and languages the current model supports.
+
+```python
+import torch
+import soundfile as sf
+from qwen_tts import Qwen3TTSModel
+
+model = Qwen3TTSModel.from_pretrained(
+ "Qwen/Qwen3-TTS-12Hz-1.7B-CustomVoice",
+ device_map="cuda:0",
+ dtype=torch.bfloat16,
+ attn_implementation="flash_attention_2",
+)
+
+# single inference
+wavs, sr = model.generate_custom_voice(
+ text="其实我真的有发现,我是一个特别善于观察别人情绪的人。",
+ language="Chinese", # Pass `Auto` (or omit) for auto language adaptive; if the target language is known, set it explicitly.
+ speaker="Vivian",
+ instruct="用特别愤怒的语气说", # Omit if not needed.
+)
+sf.write("output_custom_voice.wav", wavs[0], sr)
+
+# batch inference
+wavs, sr = model.generate_custom_voice(
+ text=[
+ "其实我真的有发现,我是一个特别善于观察别人情绪的人。",
+ "She said she would be here by noon."
+ ],
+ language=["Chinese", "English"],
+ speaker=["Vivian", "Ryan"],
+ instruct=["", "Very happy."]
+)
+sf.write("output_custom_voice_1.wav", wavs[0], sr)
+sf.write("output_custom_voice_2.wav", wavs[1], sr)
+```
+
+For `Qwen3-TTS-12Hz-1.7B/0.6B-CustomVoice` models, the supported speaker list and speaker descriptions are provided below. We recommend using each speaker’s native language for the best quality. Of course, each speaker can speak any language supported by the model.
+
+| Speaker | Voice Description | Native language |
+| --- | --- | --- |
+| Vivian | Bright, slightly edgy young female voice. | Chinese |
+| Serena | Warm, gentle young female voice. | Chinese |
+| Uncle_Fu | Seasoned male voice with a low, mellow timbre. | Chinese |
+| Dylan | Youthful Beijing male voice with a clear, natural timbre. | Chinese (Beijing Dialect) |
+| Eric | Lively Chengdu male voice with a slightly husky brightness. | Chinese (Sichuan Dialect) |
+| Ryan | Dynamic male voice with strong rhythmic drive. | English |
+| Aiden | Sunny American male voice with a clear midrange. | English |
+| Ono_Anna | Playful Japanese female voice with a light, nimble timbre. | Japanese |
+| Sohee | Warm Korean female voice with rich emotion. | Korean |
+
+#### Voice Design
+
+For the voice design model (`Qwen3-TTS-12Hz-1.7B-VoiceDesign`), you can use `generate_voice_design` to provide the target text and a natural-language `instruct` description.
+
+```python
+import torch
+import soundfile as sf
+from qwen_tts import Qwen3TTSModel
+
+model = Qwen3TTSModel.from_pretrained(
+ "Qwen/Qwen3-TTS-12Hz-1.7B-VoiceDesign",
+ device_map="cuda:0",
+ dtype=torch.bfloat16,
+ attn_implementation="flash_attention_2",
+)
+
+# single inference
+wavs, sr = model.generate_voice_design(
+ text="哥哥,你回来啦,人家等了你好久好久了,要抱抱!",
+ language="Chinese",
+ instruct="体现撒娇稚嫩的萝莉女声,音调偏高且起伏明显,营造出黏人、做作又刻意卖萌的听觉效果。",
+)
+sf.write("output_voice_design.wav", wavs[0], sr)
+
+# batch inference
+wavs, sr = model.generate_voice_design(
+ text=[
+ "哥哥,你回来啦,人家等了你好久好久了,要抱抱!",
+ "It's in the top drawer... wait, it's empty? No way, that's impossible! I'm sure I put it there!"
+ ],
+ language=["Chinese", "English"],
+ instruct=[
+ "体现撒娇稚嫩的萝莉女声,音调偏高且起伏明显,营造出黏人、做作又刻意卖萌的听觉效果。",
+ "Speak in an incredulous tone, but with a hint of panic beginning to creep into your voice."
+ ]
+)
+sf.write("output_voice_design_1.wav", wavs[0], sr)
+sf.write("output_voice_design_2.wav", wavs[1], sr)
+```
+
+#### Voice Clone
+
+For the voice clone model (`Qwen3-TTS-12Hz-1.7B/0.6B-Base`), to clone a voice and synthesize new content, you just need to provide a reference audio clip (`ref_audio`) along with its transcript (`ref_text`). `ref_audio` can be a local file path, a URL, a base64 string, or a `(numpy_array, sample_rate)` tuple. If you set `x_vector_only_mode=True`, only the speaker embedding is used so `ref_text` is not required, but cloning quality may be reduced.
+
+```python
+import torch
+import soundfile as sf
+from qwen_tts import Qwen3TTSModel
+
+model = Qwen3TTSModel.from_pretrained(
+ "Qwen/Qwen3-TTS-12Hz-1.7B-Base",
+ device_map="cuda:0",
+ dtype=torch.bfloat16,
+ attn_implementation="flash_attention_2",
+)
+
+ref_audio = "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen3-TTS-Repo/clone.wav"
+ref_text = "Okay. Yeah. I resent you. I love you. I respect you. But you know what? You blew it! And thanks to you."
+
+wavs, sr = model.generate_voice_clone(
+ text="I am solving the equation: x = [-b ± √(b²-4ac)] / 2a? Nobody can — it's a disaster (◍•͈⌔•͈◍), very sad!",
+ language="English",
+ ref_audio=ref_audio,
+ ref_text=ref_text,
+)
+sf.write("output_voice_clone.wav", wavs[0], sr)
+```
+
+If you need to reuse the same reference prompt across multiple generations (to avoid recomputing prompt features), build it once with `create_voice_clone_prompt` and pass it via `voice_clone_prompt`.
+
+```python
+prompt_items = model.create_voice_clone_prompt(
+ ref_audio=ref_audio,
+ ref_text=ref_text,
+ x_vector_only_mode=False,
+)
+wavs, sr = model.generate_voice_clone(
+ text=["Sentence A.", "Sentence B."],
+ language=["English", "English"],
+ voice_clone_prompt=prompt_items,
+)
+sf.write("output_voice_clone_1.wav", wavs[0], sr)
+sf.write("output_voice_clone_2.wav", wavs[1], sr)
+```
+
+For more examples of reusable voice clone prompts, batch cloning, and batch inference, please refer to the [example codes](https://github.com/QwenLM/Qwen3-TTS/blob/main/examples/test_model_12hz_base.py). With those examples and the `generate_voice_clone` function description, you can explore more advanced usage patterns.
+
+#### Voice Design then Clone
+
+If you want a designed voice that you can reuse like a cloned speaker, a practical workflow is: (1) use the **VoiceDesign** model to synthesize a short reference clip that matches your target persona, (2) feed that clip into `create_voice_clone_prompt` to build a reusable prompt, and then (3) call `generate_voice_clone` with `voice_clone_prompt` to generate new content without re-extracting features every time. This is especially useful when you want a consistent character voice across many lines.
+
+```python
+import torch
+import soundfile as sf
+from qwen_tts import Qwen3TTSModel
+
+# create a reference audio in the target style using the VoiceDesign model
+design_model = Qwen3TTSModel.from_pretrained(
+ "Qwen/Qwen3-TTS-12Hz-1.7B-VoiceDesign",
+ device_map="cuda:0",
+ dtype=torch.bfloat16,
+ attn_implementation="flash_attention_2",
+)
+
+ref_text = "H-hey! You dropped your... uh... calculus notebook? I mean, I think it's yours? Maybe?"
+ref_instruct = "Male, 17 years old, tenor range, gaining confidence - deeper breath support now, though vowels still tighten when nervous"
+ref_wavs, sr = design_model.generate_voice_design(
+ text=ref_text,
+ language="English",
+ instruct=ref_instruct
+)
+sf.write("voice_design_reference.wav", ref_wavs[0], sr)
+
+# build a reusable clone prompt from the voice design reference
+clone_model = Qwen3TTSModel.from_pretrained(
+ "Qwen/Qwen3-TTS-12Hz-1.7B-Base",
+ device_map="cuda:0",
+ dtype=torch.bfloat16,
+ attn_implementation="flash_attention_2",
+)
+
+voice_clone_prompt = clone_model.create_voice_clone_prompt(
+ ref_audio=(ref_wavs[0], sr), # or "voice_design_reference.wav"
+ ref_text=ref_text,
+)
+
+sentences = [
+ "No problem! I actually... kinda finished those already? If you want to compare answers or something...",
+ "What? No! I mean yes but not like... I just think you're... your titration technique is really precise!",
+]
+
+# reuse it for multiple single calls
+wavs, sr = clone_model.generate_voice_clone(
+ text=sentences[0],
+ language="English",
+ voice_clone_prompt=voice_clone_prompt,
+)
+sf.write("clone_single_1.wav", wavs[0], sr)
+
+wavs, sr = clone_model.generate_voice_clone(
+ text=sentences[1],
+ language="English",
+ voice_clone_prompt=voice_clone_prompt,
+)
+sf.write("clone_single_2.wav", wavs[0], sr)
+
+# or batch generate in one call
+wavs, sr = clone_model.generate_voice_clone(
+ text=sentences,
+ language=["English", "English"],
+ voice_clone_prompt=voice_clone_prompt,
+)
+for i, w in enumerate(wavs):
+ sf.write(f"clone_batch_{i}.wav", w, sr)
+```
+
+#### Tokenizer Encode and Decode
+
+If you only want to encode and decode audio for transport or training and so on, `Qwen3TTSTokenizer` supports encode/decode with paths, URLs, numpy waveforms, and dict/list payloads, for example:
+
+```python
+import soundfile as sf
+from qwen_tts import Qwen3TTSTokenizer
+
+tokenizer = Qwen3TTSTokenizer.from_pretrained(
+ "Qwen/Qwen3-TTS-Tokenizer-12Hz",
+ device_map="cuda:0",
+)
+
+enc = tokenizer.encode("https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen3-TTS-Repo/tokenizer_demo_1.wav")
+wavs, sr = tokenizer.decode(enc)
+sf.write("decode_output.wav", wavs[0], sr)
+```
+
+For more tokenizer examples (including different input formats and batch usage), please refer to the [example codes](https://github.com/QwenLM/Qwen3-TTS/blob/main/examples/test_tokenizer_12hz.py). With those examples and the description for `Qwen3TTSTokenizer`, you can explore more advanced usage patterns.
+
+### Launch Local Web UI Demo
+
+To launch the Qwen3-TTS web ui demo, simply install the `qwen-tts` package and run `qwen-tts-demo`. Use the command below for help:
+
+```bash
+qwen-tts-demo --help
+```
+
+To launch the demo, you can use the following commands:
+
+```bash
+# CustomVoice model
+qwen-tts-demo Qwen/Qwen3-TTS-12Hz-1.7B-CustomVoice --ip 0.0.0.0 --port 8000
+# VoiceDesign model
+qwen-tts-demo Qwen/Qwen3-TTS-12Hz-1.7B-VoiceDesign --ip 0.0.0.0 --port 8000
+# Base model
+qwen-tts-demo Qwen/Qwen3-TTS-12Hz-1.7B-Base --ip 0.0.0.0 --port 8000
+```
+
+And then open `http://:8000`, or access it via port forwarding in tools like VS Code.
+
+#### Base Model HTTPS Notes
+
+To avoid browser microphone permission issues after deploying the server, for Base model deployments, it is recommended/required to run the gradio service over **HTTPS** (especially when accessed remotely or behind modern browsers/gateways). Use `--ssl-certfile` and `--ssl-keyfile` to enable HTTPS. First we need to generate a private key and a self-signed cert (valid for 365 days):
+
+```bash
+openssl req -x509 -newkey rsa:2048 \
+ -keyout key.pem -out cert.pem \
+ -days 365 -nodes \
+ -subj "/CN=localhost"
+```
+
+Then run the demo with HTTPS:
+
+```bash
+qwen-tts-demo Qwen/Qwen3-TTS-12Hz-1.7B-Base \
+ --ip 0.0.0.0 --port 8000 \
+ --ssl-certfile cert.pem \
+ --ssl-keyfile key.pem \
+ --no-ssl-verify
+```
+
+And open `https://:8000` to experience it. If your browser shows a warning, it’s expected for self-signed certificates. For production, use a real certificate.
+
+### DashScope API Usage
+
+To further explore Qwen3-TTS, we encourage you to try our DashScope API for a faster and more efficient experience. For detailed API information and documentation, please refer to the following:
+
+| API Description | API Documentation (Mainland China) | API Documentation (International) |
+|------------------|-----------------------------------|------------------------------------|
+| Real-time API for Qwen3-TTS of custom voice model. | [https://help.aliyun.com/zh/model-studio/qwen-tts-realtime](https://help.aliyun.com/zh/model-studio/qwen-tts-realtime) | [https://www.alibabacloud.com/help/en/model-studio/qwen-tts-realtime](https://www.alibabacloud.com/help/en/model-studio/qwen-tts-realtime) |
+| Real-time API for Qwen3-TTS of voice clone model. | [https://help.aliyun.com/zh/model-studio/qwen-tts-voice-cloning](https://help.aliyun.com/zh/model-studio/qwen-tts-voice-cloning) | [https://www.alibabacloud.com/help/en/model-studio/qwen-tts-voice-cloning](https://www.alibabacloud.com/help/en/model-studio/qwen-tts-voice-cloning) |
+| Real-time API for Qwen3-TTS of voice design model. | [https://help.aliyun.com/zh/model-studio/qwen-tts-voice-design](https://help.aliyun.com/zh/model-studio/qwen-tts-voice-design) | [https://www.alibabacloud.com/help/en/model-studio/qwen-tts-voice-design](https://www.alibabacloud.com/help/en/model-studio/qwen-tts-voice-design) |
+
+
+## vLLM Usage
+
+vLLM officially provides day-0 support for Qwen3-TTS! Welcome to use vLLM-Omni for Qwen3-TTS deployment and inference. For installation and more details, please check [vLLM-Omni official documentation](https://docs.vllm.ai/projects/vllm-omni/en/latest/getting_started/quickstart/#installation). Now only offline inference is supported. Online serving will be supported later, and vLLM-Omni will continue to offer support and optimization for Qwen3-TTS in areas such as inference speed and streaming capabilities.
+
+### Offline Inference
+You can use vLLM-Omni to inference Qwen3-TTS locally, we provide examples in [vLLM-Omni repo](https://github.com/vllm-project/vllm-omni/tree/main/examples/offline_inference/qwen3_tts) which can generate audio output:
+```bash
+# git clone https://github.com/vllm-project/vllm-omni.git
+
+# cd vllm-omni/examples/offline_inference/qwen3_tts
+
+# Run a single sample with CustomVoice task
+python end2end.py --query-type CustomVoice
+
+# Batch sample (multiple prompts in one run) with CustomVoice task:
+python end2end.py --query-type CustomVoice --use-batch-sample
+
+# Run a single sample with VoiceDesign task
+python end2end.py --query-type VoiceDesign
+
+# Batch sample (multiple prompts in one run) with VoiceDesign task:
+python end2end.py --query-type VoiceDesign --use-batch-sample
+
+# Run a single sample with Base task in icl mode-tag
+python end2end.py --query-type Base --mode-tag icl
+```
+
+## Evaluation
+
+During evaluation, we ran inference for all models with `dtype=torch.bfloat16` and set `max_new_tokens=2048`. All other sampling parameters used the defaults from the checkpoint’s `generate_config.json`. For the Seed-Test and InstructTTS-Eval test sets, we set `language="auto"`, while for all other test sets we explicitly passed the corresponding `language`. The detailed results are shown below.
+
+
+
+Speech Generation Benchmarks
+
+*Zero-shot speech generation on the Seed-TTS test set. Performance is measured by Word Error Rate (WER, ↓), where lower is better.*
+
+
+
+
+ | Datasets |
+ Model |
+ Performance |
+
+
+ | Content Consistency |
+
+
+
+
+ SEED
test-zh | test-en |
+ Seed-TTS (Anastassiou et al., 2024) |
+ 1.12 |
+ 2.25 |
+
+
+ | MaskGCT (Wang et al., 2024) |
+ 2.27 |
+ 2.62 |
+
+
+ | E2 TTS (Eskimez et al., 2024) |
+ 1.97 |
+ 2.19 |
+
+
+ | F5-TTS (Chen et al., 2024) |
+ 1.56 |
+ 1.83 |
+
+
+ | Spark TTS (Wang et al., 2025) |
+ 1.20 |
+ 1.98 |
+
+
+ | Llasa-8B (Ye et al., 2025b) |
+ 1.59 |
+ 2.97 |
+
+
+ | KALL-E (Xia et al., 2024) |
+ 0.96 |
+ 1.94 |
+
+
+ | FireRedTTS 2 (Xie et al., 2025) |
+ 1.14 |
+ 1.95 |
+
+
+ | CosyVoice 3 (Du et al., 2025) |
+ 0.71 |
+ 1.45 |
+
+
+ | MiniMax-Speech (Zhang et al., 2025a) |
+ 0.83 |
+ 1.65 |
+
+
+ | Qwen3-TTS-25Hz-0.6B-Base |
+ 1.18 |
+ 1.64 |
+
+
+ | Qwen3-TTS-25Hz-1.7B-Base |
+ 1.10 |
+ 1.49 |
+
+
+ | Qwen3-TTS-12Hz-0.6B-Base |
+ 0.92 |
+ 1.32 |
+
+
+ | Qwen3-TTS-12Hz-1.7B-Base |
+ 0.77 |
+ 1.24 |
+
+
+
+
+
+
+*Multilingual speech generation on the TTS multilingual test set. Performance is measured by Word Error Rate (WER, ↓) for content consistency and Cosine Similarity (SIM, ↑) for speaker similarity.*
+
+
+
+
+ | Language |
+ Qwen3-TTS-25Hz |
+ Qwen3-TTS-12Hz |
+ MiniMax |
+ ElevenLabs |
+
+
+ | 0.6B-Base |
+ 1.7B-Base |
+ 0.6B-Base |
+ 1.7B-Base |
+
+
+
+
+ | Content Consistency |
+
+
+ | Chinese |
+ 1.108 |
+ 0.777 |
+ 1.145 |
+ 0.928 |
+ 2.252 |
+ 16.026 |
+
+
+ | English |
+ 1.048 |
+ 1.014 |
+ 0.836 |
+ 0.934 |
+ 2.164 |
+ 2.339 |
+
+
+ | German |
+ 1.501 |
+ 0.960 |
+ 1.089 |
+ 1.235 |
+ 1.906 |
+ 0.572 |
+
+
+ | Italian |
+ 1.169 |
+ 1.105 |
+ 1.534 |
+ 0.948 |
+ 1.543 |
+ 1.743 |
+
+
+ | Portuguese |
+ 2.046 |
+ 1.778 |
+ 2.254 |
+ 1.526 |
+ 1.877 |
+ 1.331 |
+
+
+ | Spanish |
+ 2.031 |
+ 1.491 |
+ 1.491 |
+ 1.126 |
+ 1.029 |
+ 1.084 |
+
+
+ | Japanese |
+ 4.189 |
+ 5.121 |
+ 6.404 |
+ 3.823 |
+ 3.519 |
+ 10.646 |
+
+
+ | Korean |
+ 2.852 |
+ 2.631 |
+ 1.741 |
+ 1.755 |
+ 1.747 |
+ 1.865 |
+
+
+ | French |
+ 2.852 |
+ 2.631 |
+ 2.931 |
+ 2.858 |
+ 4.099 |
+ 5.216 |
+
+
+ | Russian |
+ 5.957 |
+ 4.535 |
+ 4.458 |
+ 3.212 |
+ 4.281 |
+ 3.878 |
+
+
+ | Speaker Similarity |
+
+
+ | Chinese |
+ 0.797 |
+ 0.796 |
+ 0.811 |
+ 0.799 |
+ 0.780 |
+ 0.677 |
+
+
+ | English |
+ 0.811 |
+ 0.815 |
+ 0.829 |
+ 0.775 |
+ 0.756 |
+ 0.613 |
+
+
+ | German |
+ 0.749 |
+ 0.737 |
+ 0.769 |
+ 0.775 |
+ 0.733 |
+ 0.614 |
+
+
+ | Italian |
+ 0.722 |
+ 0.718 |
+ 0.792 |
+ 0.817 |
+ 0.699 |
+ 0.579 |
+
+
+ | Portuguese |
+ 0.790 |
+ 0.783 |
+ 0.794 |
+ 0.817 |
+ 0.805 |
+ 0.711 |
+
+
+ | Spanish |
+ 0.732 |
+ 0.731 |
+ 0.812 |
+ 0.814 |
+ 0.762 |
+ 0.615 |
+
+
+ | Japanese |
+ 0.810 |
+ 0.807 |
+ 0.798 |
+ 0.788 |
+ 0.776 |
+ 0.738 |
+
+
+ | Korean |
+ 0.824 |
+ 0.814 |
+ 0.812 |
+ 0.799 |
+ 0.779 |
+ 0.700 |
+
+
+ | French |
+ 0.698 |
+ 0.703 |
+ 0.700 |
+ 0.714 |
+ 0.628 |
+ 0.535 |
+
+
+ | Russian |
+ 0.734 |
+ 0.744 |
+ 0.781 |
+ 0.792 |
+ 0.761 |
+ 0.676 |
+
+
+
+
+
+
+*Cross-lingual speech generation on the Cross-Lingual benchmark. Performance is measured by Mixed Error Rate (WER for English, CER for others, ↓).*
+
+
+
+
+ | Task |
+ Qwen3-TTS-25Hz-1.7B-Base |
+ Qwen3-TTS-12Hz-1.7B-Base |
+ CosyVoice3 |
+ CosyVoice2 |
+
+
+
+
+ | en-to-zh |
+ 5.66 |
+ 4.77 |
+ 5.09 |
+ 13.5 |
+
+
+ | ja-to-zh |
+ 3.92 |
+ 3.43 |
+ 3.05 |
+ 48.1 |
+
+
+ | ko-to-zh |
+ 1.14 |
+ 1.08 |
+ 1.06 |
+ 7.70 |
+
+
+ | zh-to-en |
+ 2.91 |
+ 2.77 |
+ 2.98 |
+ 6.47 |
+
+
+ | ja-to-en |
+ 3.95 |
+ 3.04 |
+ 4.20 |
+ 17.1 |
+
+
+ | ko-to-en |
+ 3.48 |
+ 3.09 |
+ 4.19 |
+ 11.2 |
+
+
+ | zh-to-ja |
+ 9.29 |
+ 8.40 |
+ 7.08 |
+ 13.1 |
+
+
+ | en-to-ja |
+ 7.74 |
+ 7.21 |
+ 6.80 |
+ 14.9 |
+
+
+ | ko-to-ja |
+ 4.17 |
+ 3.67 |
+ 3.93 |
+ 5.86 |
+
+
+ | zh-to-ko |
+ 8.12 |
+ 4.82 |
+ 14.4 |
+ 24.8 |
+
+
+ | en-to-ko |
+ 6.83 |
+ 5.14 |
+ 5.87 |
+ 21.9 |
+
+
+ | ja-to-ko |
+ 6.86 |
+ 5.59 |
+ 7.92 |
+ 21.5 |
+
+
+
+
+
+
+*Controllable speech generation on InstructTTSEval. Performance is measured by Attribute Perception and Synthesis accuracy (APS), Description-Speech Consistency (DSD), and Response Precision (RP).*
+
+
+
+
+ | Type |
+ Model |
+ InstructTTSEval-ZH |
+ InstructTTSEval-EN |
+
+
+ | APS (↑) |
+ DSD (↑) |
+ RP (↑) |
+ APS (↑) |
+ DSD (↑) |
+ RP (↑) |
+
+
+
+
+ Target
Speaker |
+ Gemini-flash |
+ 88.2 |
+ 90.9 |
+ 77.3 |
+ 92.3 |
+ 93.8 |
+ 80.1 |
+
+
+ | Gemini-pro |
+ 89.0 |
+ 90.1 |
+ 75.5 |
+ 87.6 |
+ 86.0 |
+ 67.2 |
+
+
+ | Qwen3TTS-25Hz-1.7B-CustomVoice |
+ 83.1 |
+ 75.0 |
+ 63.0 |
+ 79.0 |
+ 82.8 |
+ 69.3 |
+
+
+ | Qwen3TTS-12Hz-1.7B-CustomVoice |
+ 83.0 |
+ 77.8 |
+ 61.2 |
+ 77.3 |
+ 77.1 |
+ 63.7 |
+
+
+ | GPT-4o-mini-tts |
+ 54.9 |
+ 52.3 |
+ 46.0 |
+ 76.4 |
+ 74.3 |
+ 54.8 |
+
+
+ Voice
Design |
+ Qwen3TTS-12Hz-1.7B-VD |
+ 85.2 |
+ 81.1 |
+ 65.1 |
+ 82.9 |
+ 82.4 |
+ 68.4 |
+
+
+ | Mimo-Audio-7B-Instruct (Zhang et al., 2025b) |
+ 75.7 |
+ 74.3 |
+ 61.5 |
+ 80.6 |
+ 77.6 |
+ 59.5 |
+
+
+ | VoiceSculptor (Hu et al., 2026) |
+ 75.7 |
+ 64.7 |
+ 61.5 |
+ - |
+ - |
+ - |
+
+
+ | Hume |
+ - |
+ - |
+ - |
+ 83.0 |
+ 75.3 |
+ 54.3 |
+
+
+ | VoxInstruct (Zhou et al., 2024) |
+ 47.5 |
+ 52.3 |
+ 42.6 |
+ 54.9 |
+ 57.0 |
+ 39.3 |
+
+
+ | Parler-tts-mini (Lyth & King, 2024) |
+ - |
+ - |
+ - |
+ 63.4 |
+ 48.7 |
+ 28.6 |
+
+
+ | Parler-tts-large (Lyth & King, 2024) |
+ - |
+ - |
+ - |
+ 60.0 |
+ 45.9 |
+ 31.2 |
+
+
+ | PromptTTS (Guo et al., 2023) |
+ - |
+ - |
+ - |
+ 64.3 |
+ 47.2 |
+ 31.4 |
+
+
+ | PromptStyle (Liu et al., 2023) |
+ - |
+ - |
+ - |
+ 57.4 |
+ 46.4 |
+ 30.9 |
+
+
+
+
+
+
+*Target-Speaker Multilingual Speech Generation on the TTS multilingual test set. Performance is measured by Word Error Rate (WER, ↓).*
+
+
+
+
+ | Language |
+ Qwen3-TTS-25Hz |
+ Qwen3-TTS-12Hz |
+ GPT-4o-Audio
Preview |
+
+
+ | 0.6B-CustomVoice |
+ 1.7B-CustomVoice |
+ 0.6B-CustomVoice |
+ 1.7B-CustomVoice |
+
+
+
+
+ | Chinese |
+ 0.874 |
+ 0.708 |
+ 0.944 |
+ 0.903 |
+ 3.519 |
+
+
+ | English |
+ 1.332 |
+ 0.936 |
+ 1.188 |
+ 0.899 |
+ 2.197 |
+
+
+ | German |
+ 0.990 |
+ 0.634 |
+ 2.722 |
+ 1.057 |
+ 1.161 |
+
+
+ | Italian |
+ 1.861 |
+ 1.271 |
+ 2.545 |
+ 1.362 |
+ 1.194 |
+
+
+ | Portuguese |
+ 1.728 |
+ 1.854 |
+ 3.219 |
+ 2.681 |
+ 1.504 |
+
+
+ | Spanish |
+ 1.309 |
+ 1.284 |
+ 1.154 |
+ 1.330 |
+ 4.000 |
+
+
+ | Japanese |
+ 3.875 |
+ 4.518 |
+ 6.877 |
+ 4.924 |
+ 5.001 |
+
+
+ | Korean |
+ 2.202 |
+ 2.274 |
+ 3.053 |
+ 1.741 |
+ 2.763 |
+
+
+ | French |
+ 3.865 |
+ 3.080 |
+ 3.841 |
+ 3.781 |
+ 3.605 |
+
+
+ | Russian |
+ 6.529 |
+ 4.444 |
+ 5.809 |
+ 4.734 |
+ 5.250 |
+
+
+
+
+
+
+*Long speech generation results. Performance is measured by Word Error Rate (WER, ↓).*
+
+
+
+
+ | Datasets |
+ Model |
+ Performance |
+
+
+ | Content Consistency |
+
+
+
+
+ | long-zh | long-en |
+ Higgs-Audio-v2 (chunk) (Boson AI, 2025) |
+ 5.505 |
+ 6.917 |
+
+
+ | VibeVoice (Peng et al., 2025) |
+ 22.619 |
+ 1.780 |
+
+
+ | VoxCPM (Zhou et al., 2025) |
+ 4.835 |
+ 7.474 |
+
+
+ | Qwen3-TTS-25Hz-1.7B-CustomVoice |
+ 1.517 |
+ 1.225 |
+
+
+ | Qwen3-TTS-12Hz-1.7B-CustomVoice |
+ 2.356 |
+ 2.812 |
+
+
+
+
+
+
+
+Speech Tokenizer Benchmarks
+
+*Comparison between different supervised semantic speech tokenizers on ASR Task.*
+
+
+
+
+ | Model |
+ Codebook Size |
+ FPS |
+ C.V. EN |
+ C.V. CN |
+ Fluers EN |
+ Fluers CN |
+
+
+
+
+ | S3 Tokenizer(VQ) (Du et al., 2024a) |
+ 4096 |
+ 50 |
+ 12.06 |
+ 15.38 |
+ - |
+ - |
+
+
+ | S3 Tokenizer(VQ) (Du et al., 2024a) |
+ 4096 |
+ 25 |
+ 11.56 |
+ 18.26 |
+ 7.65 |
+ 5.03 |
+
+
+ | S3 Tokenizer(FSQ) (Du et al., 2024a) |
+ 6561 |
+ 25 |
+ 10.67 |
+ 7.29 |
+ 6.58 |
+ 4.43 |
+
+
+ | Qwen-TTS-Tokenizer-25Hz (Stage 1) |
+ 32768 |
+ 25 |
+ 7.51 |
+ 10.73 |
+ 3.07 |
+ 4.23 |
+
+
+ | Qwen-TTS-Tokenizer-25Hz (Stage 2) |
+ 32768 |
+ 25 |
+ 10.40 |
+ 14.99 |
+ 4.14 |
+ 4.67 |
+
+
+
+
+
+
+*Comparison between different semantic-related speech tokenizers.*
+
+
+
+
+ | Model |
+ NQ |
+ Codebook Size |
+ FPS |
+ PESQ_WB |
+ PESQ_NB |
+ STOI |
+ UTMOS |
+ SIM |
+
+
+
+
+ | SpeechTokenizer (Zhang et al., 2023a) |
+ 8 |
+ 1024 |
+ 50 |
+ 2.60 |
+ 3.05 |
+ 0.92 |
+ 3.90 |
+ 0.85 |
+
+
+ | X-codec (Ye et al., 2025a) |
+ 2 |
+ 1024 |
+ 50 |
+ 2.68 |
+ 3.27 |
+ 0.86 |
+ 4.11 |
+ 0.84 |
+
+
+ | X-codec 2 (Ye et al., 2025b) |
+ 1 |
+ 65536 |
+ 50 |
+ 2.43 |
+ 3.04 |
+ 0.92 |
+ 4.13 |
+ 0.82 |
+
+
+ | XY-Tokenizer (Gong et al., 2025) |
+ 8 |
+ 1024 |
+ 12.5 |
+ 2.41 |
+ 3.00 |
+ 0.91 |
+ 3.98 |
+ 0.83 |
+
+
+ | Mimi (Défossez et al., 2024) |
+ 16 |
+ 2048 |
+ 12.5 |
+ 2.88 |
+ 3.42 |
+ 0.94 |
+ 3.87 |
+ 0.87 |
+
+
+ | FireredTTS 2 Tokenizer (Xie et al., 2025) |
+ 16 |
+ 2048 |
+ 12.5 |
+ 2.73 |
+ 3.28 |
+ 0.94 |
+ 3.88 |
+ 0.87 |
+
+
+ | Qwen-TTS-Tokenizer-12Hz |
+ 16 |
+ 2048 |
+ 12.5 |
+ 3.21 |
+ 3.68 |
+ 0.96 |
+ 4.16 |
+ 0.95 |
+
+
+
+
+
+
+
+## Citation
+
+If you find our paper and code useful in your research, please consider giving a star :star: and citation :pencil: :)
+
+```BibTeX
+@article{Qwen3-TTS,
+ title={Qwen3-TTS Technical Report},
+ author={Hangrui Hu and Xinfa Zhu and Ting He and Dake Guo and Bin Zhang and Xiong Wang and Zhifang Guo and Ziyue Jiang and Hongkun Hao and Zishan Guo and Xinyu Zhang and Pei Zhang and Baosong Yang and Jin Xu and Jingren Zhou and Junyang Lin},
+ journal={arXiv preprint arXiv:2601.15621},
+ year={2026}
+}
+```
+
+
\ No newline at end of file
diff --git a/SourceAssets/Audio/Voice/qwen-profile.json b/SourceAssets/Audio/Voice/qwen-profile.json
new file mode 100644
index 0000000..f27b4d1
--- /dev/null
+++ b/SourceAssets/Audio/Voice/qwen-profile.json
@@ -0,0 +1,24 @@
+{
+ "schemaVersion": 1,
+ "modelId": "Qwen/Qwen3-TTS-12Hz-1.7B-CustomVoice",
+ "modelRevision": "0c0e3051f131929182e2c023b9537f8b1c68adfe",
+ "language": "Korean",
+ "speaker": "Sohee",
+ "instruct": "5~7세 아이에게 이야기하듯 따뜻하고 밝게, 천천히 또렷하게 읽어 주세요. 숫자는 정확하게 읽고 과장된 비명이나 웃음소리는 넣지 마세요.",
+ "device": "cuda:0",
+ "dtype": "bfloat16",
+ "attention": "sdpa",
+ "seed": 42,
+ "generationParameters": {
+ "do_sample": true,
+ "repetition_penalty": 1.05,
+ "temperature": 0.9,
+ "top_p": 1,
+ "top_k": 50,
+ "subtalker_dosample": true,
+ "subtalker_temperature": 0.9,
+ "subtalker_top_p": 1,
+ "subtalker_top_k": 50,
+ "max_new_tokens": 8192
+ }
+}
diff --git a/SourceAssets/Audio/Voice/voice-catalog.json b/SourceAssets/Audio/Voice/voice-catalog.json
new file mode 100644
index 0000000..7861e15
--- /dev/null
+++ b/SourceAssets/Audio/Voice/voice-catalog.json
@@ -0,0 +1,421 @@
+{
+ "schemaVersion": 1,
+ "clips": [
+ {
+ "id": "count_01",
+ "text": "하나",
+ "usage": "count",
+ "stageIds": [
+ 1,
+ 2,
+ 3,
+ 4,
+ 5,
+ 6,
+ 7,
+ 8,
+ 9,
+ 10,
+ 11,
+ 12,
+ 13,
+ 14,
+ 15,
+ 16,
+ 17,
+ 18,
+ 19,
+ 20,
+ 21,
+ 22,
+ 23,
+ 24,
+ 25,
+ 26,
+ 27,
+ 28,
+ 29,
+ 30
+ ],
+ "required": true
+ },
+ {
+ "id": "count_02",
+ "text": "둘",
+ "usage": "count",
+ "stageIds": [
+ 1,
+ 2,
+ 3,
+ 4,
+ 5,
+ 6,
+ 7,
+ 8,
+ 9,
+ 10,
+ 11,
+ 12,
+ 13,
+ 14,
+ 15,
+ 16,
+ 17,
+ 18,
+ 19,
+ 20,
+ 21,
+ 22,
+ 23,
+ 24,
+ 25,
+ 26,
+ 27,
+ 28,
+ 29,
+ 30
+ ],
+ "required": false
+ },
+ {
+ "id": "count_03",
+ "text": "셋",
+ "usage": "count",
+ "stageIds": [
+ 1,
+ 2,
+ 3,
+ 4,
+ 5,
+ 6,
+ 7,
+ 8,
+ 9,
+ 10,
+ 11,
+ 12,
+ 13,
+ 14,
+ 15,
+ 16,
+ 17,
+ 18,
+ 19,
+ 20,
+ 21,
+ 22,
+ 23,
+ 24,
+ 25,
+ 26,
+ 27,
+ 28,
+ 29,
+ 30
+ ],
+ "required": false
+ },
+ {
+ "id": "count_04",
+ "text": "넷",
+ "usage": "count",
+ "stageIds": [
+ 1,
+ 2,
+ 3,
+ 4,
+ 5,
+ 6,
+ 7,
+ 8,
+ 9,
+ 10,
+ 11,
+ 12,
+ 13,
+ 14,
+ 15,
+ 16,
+ 17,
+ 18,
+ 19,
+ 20,
+ 21,
+ 22,
+ 23,
+ 24,
+ 25,
+ 26,
+ 27,
+ 28,
+ 29,
+ 30
+ ],
+ "required": false
+ },
+ {
+ "id": "count_05",
+ "text": "다섯",
+ "usage": "count",
+ "stageIds": [
+ 1,
+ 2,
+ 3,
+ 4,
+ 5,
+ 6,
+ 7,
+ 8,
+ 9,
+ 10,
+ 11,
+ 12,
+ 13,
+ 14,
+ 15,
+ 16,
+ 17,
+ 18,
+ 19,
+ 20,
+ 21,
+ 22,
+ 23,
+ 24,
+ 25,
+ 26,
+ 27,
+ 28,
+ 29,
+ 30
+ ],
+ "required": false
+ },
+ {
+ "id": "count_06",
+ "text": "여섯",
+ "usage": "count",
+ "stageIds": [
+ 1,
+ 2,
+ 3,
+ 4,
+ 5,
+ 6,
+ 7,
+ 8,
+ 9,
+ 10,
+ 11,
+ 12,
+ 13,
+ 14,
+ 15,
+ 16,
+ 17,
+ 18,
+ 19,
+ 20,
+ 21,
+ 22,
+ 23,
+ 24,
+ 25,
+ 26,
+ 27,
+ 28,
+ 29,
+ 30
+ ],
+ "required": false
+ },
+ {
+ "id": "count_07",
+ "text": "일곱",
+ "usage": "count",
+ "stageIds": [
+ 1,
+ 2,
+ 3,
+ 4,
+ 5,
+ 6,
+ 7,
+ 8,
+ 9,
+ 10,
+ 11,
+ 12,
+ 13,
+ 14,
+ 15,
+ 16,
+ 17,
+ 18,
+ 19,
+ 20,
+ 21,
+ 22,
+ 23,
+ 24,
+ 25,
+ 26,
+ 27,
+ 28,
+ 29,
+ 30
+ ],
+ "required": false
+ },
+ {
+ "id": "count_08",
+ "text": "여덟",
+ "usage": "count",
+ "stageIds": [
+ 1,
+ 2,
+ 3,
+ 4,
+ 5,
+ 6,
+ 7,
+ 8,
+ 9,
+ 10,
+ 11,
+ 12,
+ 13,
+ 14,
+ 15,
+ 16,
+ 17,
+ 18,
+ 19,
+ 20,
+ 21,
+ 22,
+ 23,
+ 24,
+ 25,
+ 26,
+ 27,
+ 28,
+ 29,
+ 30
+ ],
+ "required": false
+ },
+ {
+ "id": "count_09",
+ "text": "아홉",
+ "usage": "count",
+ "stageIds": [
+ 1,
+ 2,
+ 3,
+ 4,
+ 5,
+ 6,
+ 7,
+ 8,
+ 9,
+ 10,
+ 11,
+ 12,
+ 13,
+ 14,
+ 15,
+ 16,
+ 17,
+ 18,
+ 19,
+ 20,
+ 21,
+ 22,
+ 23,
+ 24,
+ 25,
+ 26,
+ 27,
+ 28,
+ 29,
+ 30
+ ],
+ "required": false
+ },
+ {
+ "id": "count_10",
+ "text": "열",
+ "usage": "count",
+ "stageIds": [
+ 1,
+ 2,
+ 3,
+ 4,
+ 5,
+ 6,
+ 7,
+ 8,
+ 9,
+ 10,
+ 11,
+ 12,
+ 13,
+ 14,
+ 15,
+ 16,
+ 17,
+ 18,
+ 19,
+ 20,
+ 21,
+ 22,
+ 23,
+ 24,
+ 25,
+ 26,
+ 27,
+ 28,
+ 29,
+ 30
+ ],
+ "required": false
+ },
+ {
+ "id": "guide_collect",
+ "text": "친구를 찾아 끌어와 볼까?",
+ "usage": "guide_collect",
+ "stageIds": [
+ 1,
+ 2,
+ 3,
+ 4,
+ 5,
+ 16,
+ 17,
+ 18,
+ 19,
+ 20
+ ],
+ "required": true
+ },
+ {
+ "id": "guide_count",
+ "text": "모두 모았네! 하나씩 눌러 세어 보자.",
+ "usage": "guide_count",
+ "stageIds": [
+ 1,
+ 2,
+ 3,
+ 4,
+ 5,
+ 16,
+ 17,
+ 18,
+ 19,
+ 20
+ ],
+ "required": true
+ }
+ ]
+}
diff --git a/docs/qwen-voice-register.md b/docs/qwen-voice-register.md
new file mode 100644
index 0000000..bfaaae0
--- /dev/null
+++ b/docs/qwen-voice-register.md
@@ -0,0 +1,49 @@
+# Korean Qwen voice drafts
+
+Status: actual local GPU synthesis and file validation completed; pronunciation, clipping at word boundaries, and voice suitability have **not been listened to or approved**. These are draft clips, not final voice assets. SFX and BGM will be supplied/selected by the user later.
+
+## Sources and conditions
+
+- Checked 2026-10-05 KST: [official Qwen3-TTS repository](https://github.com/QwenLM/Qwen3-TTS) and [model card](https://huggingface.co/Qwen/Qwen3-TTS-12Hz-1.7B-CustomVoice).
+- Model: `Qwen/Qwen3-TTS-12Hz-1.7B-CustomVoice`, revision `0c0e3051f131929182e2c023b9537f8b1c68adfe`, Korean/Sohee, existing conda environment `qwen3-tts`. Full weights, tokenizer and processor snapshot are cached outside the repository. No model/runtime generation service is included in the game.
+- Model card declares Apache-2.0. Installed qwen-tts 0.1.1 contains the Apache-2.0 code license. The actual model card and code license are recorded in `SourceAssets/Audio/Voice/licenses/`. This is a record of those published conditions, not a claim of exclusive rights to generated voices.
+- Profile contains the exact prompt, seed 42, generation parameters and device/dtype/attention; no machine-specific model cache path. Initial prompt: `5~7세 아이에게 이야기하듯 따뜻하고 밝게, 천천히 또렷하게 읽어 주세요. 숫자는 정확하게 읽고 과장된 비명이나 웃음소리는 넣지 마세요.`
+
+## Actual environment and generation evidence
+
+Only the installed CPU torch was replaced with the official `torch==2.11.0+cu128` wheel, matching the installed torchaudio 2.11.0 version. The direct torch requirement `setuptools<82` required adjusting setuptools 83.0.0 to 81.0.0. No environment recreation or unrelated upgrades.
+
+Python 3.12.15, qwen-tts 0.1.1, torch 2.11.0+cu128, torchaudio 2.11.0+cpu, transformers 4.57.3, soundfile 0.14.0, huggingface-hub 0.36.2. CUDA 12.8 / NVIDIA GeForce RTX 4080 SUPER. CUDA square/sum probe returned 140. Torch CUDA, qwen-tts and torchaudio imports succeeded. SDPA/bfloat16 worked for actual GPU synthesis without installing FlashAttention or SoX.
+
+First selected sample run `20261004T161148012934Z_47f3a009`: count_01/count_04/count_07/count_10/guide_collect. Model loading 3.214 s, peak allocated GPU memory 4,232,247,296 bytes; native output 24,000 Hz mono FLOAT WAV. Each clip's exact duration, frame count, generation time and SHA-256 are in the immutable run manifest.
+
+Expanded run `20261004T161231511126Z_aa20f404`: five prior clips reused with matching text/profile/hash; remaining numbers and guide_count actually generated. Its manifest records original run/file links, actual settings/defaults, environment, hashes and per-clip results. Successful synthesis/file validation does not imply pronunciation approval.
+
+## Runtime draft selection
+
+Drafts live under `Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/`. Source FLOAT WAVs remain unchanged; edited candidates use true polyphase resampling to 44,100 Hz mono PCM16, without speech trimming. The corresponding `edited//selection.json` links original source hash and edited/runtime hash. Existing runtime files with different contents are preserved by the preparation tool until reviewed.
+
+| ID | Duration | Status |
+| --- | ---: | --- |
+| count_01 | 0.56 s | T2 required draft, not listened |
+| guide_collect | 2.00 s | T2 required draft, not listened |
+| guide_count | 3.60 s | T2 required draft, not listened |
+| count_02,03,04,06,07,08,09,10 | 0.48–1.44 s | Optional future counting drafts, not listened |
+| count_05 | 9.12 s | Excluded from runtime selection; anomalous long silence and later energy, requires listening/recreation |
+
+`count_05` retains its complete original and edited candidate for diagnosis. A single-word number longer than two seconds is blocked from draft export by the preparation tool. This threshold is a review signal, not an automated pronunciation test.
+
+## Verification
+
+Environment commands use the existing environment Python or `conda run --no-capture-output -n qwen3-tts`, never the global Python. Commands run at the project root:
+
+```powershell
+python -m unittest discover -s tools/audio -p 'test_*.py' -v
+python tools/audio/generate_voice.py --catalog SourceAssets/Audio/Voice/voice-catalog.json --profile SourceAssets/Audio/Voice/qwen-profile.json --ids count_01,count_04,count_07,count_10,guide_collect
+python tools/audio/generate_voice.py --catalog SourceAssets/Audio/Voice/voice-catalog.json --profile SourceAssets/Audio/Voice/qwen-profile.json
+python tools/audio/generate_voice.py --catalog SourceAssets/Audio/Voice/voice-catalog.json --profile SourceAssets/Audio/Voice/qwen-profile.json --validate-only --manifest SourceAssets/Audio/Voice/generated/20261004T161231511126Z_aa20f404/manifest.json
+```
+
+Initial RED exit 1: generator module absent. GREEN: eight behavioral Python tests, exit 0, cover invalid catalogs, partial/current-profile validation, failed/nonfinite WAVs, missing/corrupt WAVs, changed clips/settings, hash tampering, preservation of originals, resampling and refusal to overwrite a different runtime draft. Actual sample synthesis, expanded synthesis and validation-only each exited 0. Validation-only neither loads nor downloads the model. Validation without IDs covers all currently required T2 clips; `--ids` records the narrower selected scope.
+
+Unity `.meta` files must be generated through actual Editor import after integration; they are not handwritten. Required follow-up: listen to each selected utterance, record reviewer/date/approved hashes, review count_05 and future stage guidance, and test queue/mix playback in the Android device build.
diff --git a/tools/audio/generate_voice.py b/tools/audio/generate_voice.py
new file mode 100644
index 0000000..374a024
--- /dev/null
+++ b/tools/audio/generate_voice.py
@@ -0,0 +1,266 @@
+"""Produce pinned local Qwen Korean voice assets; validation never loads a model."""
+import argparse
+from datetime import datetime, timezone
+import hashlib
+import importlib.metadata
+import json
+from pathlib import Path
+import re
+import sys
+import time
+import uuid
+
+import numpy as np
+import soundfile as sf
+
+MODEL_ID = 'Qwen/Qwen3-TTS-12Hz-1.7B-CustomVoice'
+
+
+def digest(value):
+ return hashlib.sha256(json.dumps(value, ensure_ascii=False, sort_keys=True,
+ separators=(',', ':')).encode('utf-8')).hexdigest()
+
+
+def file_hash(path):
+ return hashlib.sha256(Path(path).read_bytes()).hexdigest()
+
+
+def load_json(path):
+ return json.loads(Path(path).read_text(encoding='utf-8'))
+
+
+def write_json(path, value):
+ Path(path).write_text(json.dumps(value, ensure_ascii=False, indent=2) + '\n', encoding='utf-8')
+
+
+def validate_inputs(catalog, profile):
+ if catalog.get('schemaVersion') != 1 or profile.get('schemaVersion') != 1:
+ raise ValueError('catalog/profile schemaVersion must be 1')
+ clips = catalog.get('clips')
+ if not isinstance(clips, list) or not clips:
+ raise ValueError('catalog must contain clips')
+ ids = set()
+ for clip in clips:
+ clip_id = clip.get('id', '')
+ if not re.fullmatch(r'[a-z][a-z0-9_]*', clip_id) or clip_id in ids:
+ raise ValueError(f'{clip_id}: invalid or duplicate ID')
+ ids.add(clip_id)
+ if not isinstance(clip.get('text'), str) or not clip['text'].strip():
+ raise ValueError(f'{clip_id}: text is empty')
+ if not re.search('[가-힣]', clip['text']) or re.search(r'[0-9]', clip['text']):
+ raise ValueError(f'{clip_id}: use a complete Korean utterance, not numeral digits')
+ if not isinstance(clip.get('required'), bool) or not clip.get('usage'):
+ raise ValueError(f'{clip_id}: required/usage missing')
+ if not isinstance(clip.get('stageIds'), list) or not clip['stageIds'] or any(
+ type(n) is not int or n < 1 or n > 30 for n in clip['stageIds']):
+ raise ValueError(f'{clip_id}: stageIds must be within 1..30')
+ for field in ('modelRevision', 'instruct', 'device', 'dtype', 'attention', 'generationParameters', 'seed'):
+ if field not in profile:
+ raise ValueError(f'profile: missing {field}')
+ if profile.get('modelId') != MODEL_ID or profile.get('language') != 'Korean' or profile.get('speaker') != 'Sohee':
+ raise ValueError('profile must retain approved model/Korean/Sohee')
+ if not re.fullmatch('[0-9a-f]{40}', profile['modelRevision']):
+ raise ValueError('profile must pin a full model revision')
+ if profile['device'] != 'cuda:0' or profile['dtype'] not in ('bfloat16', 'float16') or profile['attention'] not in ('sdpa', 'eager'):
+ raise ValueError('profile requires approved CUDA configuration')
+ if not isinstance(profile['generationParameters'], dict) or type(profile['seed']) is not int:
+ raise ValueError('invalid generation settings')
+
+
+def select_clips(catalog, ids=None, required_only=False):
+ by_id = {c['id']: c for c in catalog['clips']}
+ if ids is None:
+ return [c for c in catalog['clips'] if not required_only or c['required']]
+ missing = set(ids) - by_id.keys()
+ if missing:
+ raise ValueError('unknown IDs: ' + ', '.join(sorted(missing)))
+ if not ids or len(ids) != len(set(ids)):
+ raise ValueError('requested IDs must be nonempty and unique')
+ return [by_id[key] for key in ids]
+
+
+def waveform_metadata(path):
+ samples, sample_rate = sf.read(path, dtype='float32', always_2d=True)
+ if sample_rate <= 0 or samples.size == 0 or not np.isfinite(samples).all():
+ raise ValueError('empty or nonfinite waveform')
+ peak = float(np.max(np.abs(samples)))
+ return {'sha256': file_hash(path), 'sampleRate': sample_rate, 'channels': samples.shape[1],
+ 'frames': samples.shape[0], 'duration': samples.shape[0] / sample_rate,
+ 'peak': peak, 'rms': float(np.sqrt(np.mean(samples ** 2))),
+ 'qualityWarnings': (['near silence'] if peak < .001 else []) +
+ (['clipping candidate'] if peak >= .999 else [])}
+
+
+def clip_errors(entry, clip, profile, root):
+ errors = []
+ if entry.get('result') not in ('generated', 'reused'):
+ return [f"{clip['id']}: no successful generation"]
+ if entry.get('textHash') != digest(clip['text']) or entry.get('settingsHash') != digest(profile):
+ errors.append(f"{clip['id']}: current text/profile differs")
+ try:
+ path = (root / entry['file']).resolve()
+ if not path.is_relative_to(root.resolve()):
+ raise ValueError('waveform escapes source directory')
+ actual = waveform_metadata(path)
+ for key in ('sha256', 'sampleRate', 'channels', 'frames', 'duration'):
+ if actual[key] != entry.get(key):
+ errors.append(f"{clip['id']}: {key} mismatch")
+ if actual['channels'] != 1:
+ errors.append(f"{clip['id']}: expected mono")
+ except (KeyError, OSError, ValueError, sf.LibsndfileError) as error:
+ errors.append(f"{clip['id']}: invalid WAV: {error}")
+ return errors
+
+
+def validate_manifest(manifest, catalog, profile, root, ids=None):
+ validate_inputs(catalog, profile)
+ requested = select_clips(catalog, ids, required_only=ids is None)
+ errors = []
+ if manifest.get('schemaVersion') != 1 or manifest.get('modelRevision') != profile['modelRevision']:
+ errors.append('manifest schema/revision differs')
+ if manifest.get('catalogHash') != digest(catalog) or manifest.get('profileHash') != digest(profile):
+ errors.append('manifest does not describe current catalog/profile')
+ entries = manifest.get('clips', [])
+ by_id = {c.get('id'): c for c in entries}
+ if len(by_id) != len(entries):
+ errors.append('manifest contains duplicate IDs')
+ for clip in requested:
+ if clip['id'] not in by_id:
+ errors.append(f"{clip['id']}: missing required/requested ID")
+ else:
+ errors.extend(clip_errors(by_id[clip['id']], clip, profile, root))
+ return errors
+
+
+def reusable_entries(root, catalog, profile):
+ result = {}
+ by_id = {c['id']: c for c in catalog['clips']}
+ for path in sorted((root / 'generated').glob('*/manifest.json'), reverse=True):
+ try:
+ manifest = load_json(path)
+ for entry in manifest.get('clips', []):
+ clip = by_id.get(entry.get('id'))
+ if clip and clip['id'] not in result and not clip_errors(entry, clip, profile, root):
+ result[clip['id']] = entry
+ except (OSError, ValueError, TypeError):
+ continue
+ return result
+
+
+def generate(catalog, profile, root, ids=None, synthesize=None, environment=None):
+ validate_inputs(catalog, profile)
+ selected = select_clips(catalog, ids)
+ root = Path(root)
+ previous = reusable_entries(root, catalog, profile)
+ run_id = datetime.now(timezone.utc).strftime('%Y%m%dT%H%M%S%fZ_') + uuid.uuid4().hex[:8]
+ run_dir = root / 'generated' / run_id
+ run_dir.mkdir(parents=True)
+ manifest = {'schemaVersion': 1, 'runId': run_id, 'createdUtc': datetime.now(timezone.utc).isoformat(),
+ 'modelRevision': profile['modelRevision'], 'catalogHash': digest(catalog),
+ 'profileHash': digest(profile), 'scope': 'selected' if ids else 'all',
+ 'requestedIds': [c['id'] for c in selected], 'environment': environment or {}, 'clips': []}
+ try:
+ for clip in selected:
+ clip_id = clip['id']
+ if clip_id in previous:
+ entry = dict(previous[clip_id], result='reused')
+ else:
+ entry = {'id': clip_id, 'textHash': digest(clip['text']), 'settingsHash': digest(profile),
+ 'originalRunId': run_id, 'file': f'generated/{run_id}/{clip_id}.wav',
+ 'review': 'not_listened'}
+ started = time.perf_counter()
+ try:
+ if synthesize is None:
+ raise ValueError('no synthesizer available')
+ samples, rate = synthesize(clip)
+ samples = np.asarray(samples, dtype=np.float32)
+ if samples.ndim != 1 or not samples.size or not np.isfinite(samples).all() or rate <= 0:
+ raise ValueError('synthesizer returned empty/nonfinite/nonmono audio')
+ path = root / entry['file']
+ sf.write(path, samples, rate, subtype='FLOAT')
+ entry.update(waveform_metadata(path), result='generated', generationSeconds=time.perf_counter() - started)
+ except Exception as error:
+ entry.update(result='failed', error=f'{type(error).__name__}: {error}')
+ manifest['clips'].append(entry)
+ write_json(run_dir / 'manifest.json', manifest)
+ print(f"{clip_id}: {entry['result']}", flush=True)
+ finally:
+ write_json(run_dir / 'manifest.json', manifest)
+ return manifest
+
+
+def load_synthesizer(profile):
+ import torch
+ from huggingface_hub import snapshot_download
+ from qwen_tts import Qwen3TTSModel
+ if not torch.cuda.is_available():
+ raise RuntimeError('CUDA unavailable; refusing an unapproved CPU fallback')
+ probe = torch.arange(8, device=profile['device'], dtype=torch.float32).square().sum().item()
+ if probe != 140:
+ raise RuntimeError('CUDA arithmetic probe failed')
+ snapshot = snapshot_download(repo_id=profile['modelId'], revision=profile['modelRevision'])
+ started = time.perf_counter()
+ torch.cuda.reset_peak_memory_stats()
+ model = Qwen3TTSModel.from_pretrained(snapshot, device_map=profile['device'],
+ dtype=getattr(torch, profile['dtype']), attn_implementation=profile['attention'])
+ model_device = str(next(model.model.parameters()).device)
+ if model_device != profile['device']:
+ raise RuntimeError(f'loaded model device {model_device} differs from requested CUDA device')
+ if 'sohee' not in [s.lower() for s in model.get_supported_speakers()] or 'korean' not in [s.lower() for s in model.get_supported_languages()]:
+ raise RuntimeError('Sohee/Korean not supported by loaded model')
+ environment = {'python': sys.version, 'packages': {name: importlib.metadata.version(name) for name in
+ ('qwen-tts', 'torch', 'torchaudio', 'transformers', 'soundfile', 'huggingface-hub')},
+ 'device': torch.cuda.get_device_name(0), 'cuda': torch.version.cuda,
+ 'modelDevice': model_device,
+ 'cudaProbe': probe, 'modelLoadSeconds': time.perf_counter() - started,
+ 'modelPeakVramBytes': torch.cuda.max_memory_allocated(),
+ 'modelDefaults': model.generate_defaults,
+ 'effectiveGenerationParameters': model._merge_generate_kwargs(**profile['generationParameters'])}
+
+ def synthesize(clip):
+ torch.manual_seed(profile['seed'])
+ torch.cuda.manual_seed_all(profile['seed'])
+ waves, rate = model.generate_custom_voice(text=clip['text'], language=profile['language'],
+ speaker=profile['speaker'], instruct=profile['instruct'],
+ non_streaming_mode=True, **profile['generationParameters'])
+ torch.cuda.synchronize()
+ environment['peakVramBytes'] = torch.cuda.max_memory_allocated()
+ return waves[0], rate
+ return synthesize, environment
+
+
+def main():
+ parser = argparse.ArgumentParser(description=__doc__)
+ parser.add_argument('--catalog', required=True, type=Path)
+ parser.add_argument('--profile', required=True, type=Path)
+ parser.add_argument('--ids', help='comma separated IDs; absent means all catalog clips')
+ parser.add_argument('--validate-only', action='store_true')
+ parser.add_argument('--manifest', type=Path)
+ args = parser.parse_args()
+ ids = args.ids.split(',') if args.ids else None
+ try:
+ catalog, profile = load_json(args.catalog), load_json(args.profile)
+ validate_inputs(catalog, profile)
+ root = args.catalog.parent
+ if args.validate_only:
+ if not args.manifest:
+ raise ValueError('--validate-only requires --manifest')
+ manifest = load_json(args.manifest)
+ errors = validate_manifest(manifest, catalog, profile, root, ids)
+ else:
+ selected = select_clips(catalog, ids)
+ reusable = reusable_entries(root, catalog, profile)
+ synthesize, environment = (None, {'modelLoad': 'not_needed'}) if all(c['id'] in reusable for c in selected) else load_synthesizer(profile)
+ manifest = generate(catalog, profile, root, ids, synthesize, environment)
+ print('Manifest: ' + str(root / 'generated' / manifest['runId'] / 'manifest.json'))
+ errors = validate_manifest(manifest, catalog, profile, root, ids)
+ print(json.dumps({'validationScope': 'selected' if ids else 'all_required', 'ids': ids,
+ 'errors': errors}, ensure_ascii=False))
+ return 1 if errors else 0
+ except Exception as error:
+ print(f'{type(error).__name__}: {error}', file=sys.stderr)
+ return 1
+
+
+if __name__ == '__main__':
+ sys.exit(main())
diff --git a/tools/audio/prepare_voice.py b/tools/audio/prepare_voice.py
new file mode 100644
index 0000000..55efaaa
--- /dev/null
+++ b/tools/audio/prepare_voice.py
@@ -0,0 +1,73 @@
+"""Resample validated source WAVs into draft Unity clips without claiming listening approval."""
+import argparse
+from pathlib import Path
+import math
+import sys
+
+import numpy as np
+import soundfile as sf
+from scipy.signal import resample_poly
+
+from generate_voice import load_json, validate_manifest, waveform_metadata, write_json
+
+
+def prepare(manifest, catalog, profile, root, target, ids=None):
+ errors = validate_manifest(manifest, catalog, profile, root, ids)
+ if errors:
+ raise ValueError('; '.join(errors))
+ selected = set(ids or [c['id'] for c in catalog['clips'] if c['required']])
+ for entry in manifest['clips']:
+ if entry['id'] in selected and entry['id'].startswith('count_') and entry['duration'] > 2:
+ raise ValueError(f"{entry['id']}: count utterance exceeds 2 seconds; review before runtime export")
+ target.mkdir(parents=True, exist_ok=True)
+ edited_dir = root / 'edited' / manifest['runId']
+ edited_dir.mkdir(parents=True, exist_ok=True)
+ selections = []
+ for entry in manifest['clips']:
+ if entry['id'] not in selected:
+ continue
+ wave, rate = sf.read(root / entry['file'], dtype='float32')
+ divisor = math.gcd(rate, 44100)
+ edited = resample_poly(wave, 44100 // divisor, rate // divisor)
+ if np.max(np.abs(edited)) >= 1:
+ raise ValueError(f"{entry['id']}: editing would clip; review level before export")
+ edited_path = edited_dir / (entry['id'] + '.wav')
+ sf.write(edited_path, edited, 44100, subtype='PCM_16')
+ runtime_path = target / edited_path.name
+ if runtime_path.exists() and runtime_path.read_bytes() != edited_path.read_bytes():
+ raise ValueError(f"{entry['id']}: existing runtime clip preserved; review new edited candidate before replacing it")
+ runtime_path.write_bytes(edited_path.read_bytes())
+ selections.append({'id': entry['id'], 'sourceRunId': entry['originalRunId'],
+ 'sourceFile': entry['file'], 'sourceSha256': entry['sha256'],
+ 'editedFile': edited_path.relative_to(root).as_posix(),
+ 'runtimeFile': 'Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice/' + runtime_path.name,
+ 'editedMetadata': waveform_metadata(edited_path),
+ 'review': 'not_listened', 'status': 'draft',
+ 'processing': 'polyphase resample to mono PCM16 44100 Hz; no speech trimming'})
+ result = {'schemaVersion': 1, 'runId': manifest['runId'], 'profileHash': manifest['profileHash'],
+ 'catalogHash': manifest['catalogHash'], 'selections': selections}
+ write_json(edited_dir / 'selection.json', result)
+ return result
+
+
+def main():
+ parser = argparse.ArgumentParser(description=__doc__)
+ parser.add_argument('--catalog', type=Path, required=True)
+ parser.add_argument('--profile', type=Path, required=True)
+ parser.add_argument('--manifest', type=Path, required=True)
+ parser.add_argument('--ids')
+ parser.add_argument('--target', type=Path, default=Path('Assets/MagnetismHeroes/UnityRuntime/Presentation/Audio/Voice'))
+ args = parser.parse_args()
+ try:
+ selection = prepare(load_json(args.manifest), load_json(args.catalog), load_json(args.profile),
+ args.catalog.parent, args.target, args.ids.split(',') if args.ids else None)
+ for clip in selection['selections']:
+ print(f"{clip['id']}: draft {clip['editedMetadata']['duration']:.3f}s {clip['editedMetadata']['sha256']}")
+ return 0
+ except Exception as error:
+ print(str(error), file=sys.stderr)
+ return 1
+
+
+if __name__ == '__main__':
+ sys.exit(main())
diff --git a/tools/audio/test_generate_voice.py b/tools/audio/test_generate_voice.py
new file mode 100644
index 0000000..d27d6ca
--- /dev/null
+++ b/tools/audio/test_generate_voice.py
@@ -0,0 +1,118 @@
+import copy
+import importlib.util
+import json
+from pathlib import Path
+import tempfile
+import unittest
+
+import numpy as np
+import soundfile as sf
+
+SPEC = importlib.util.spec_from_file_location('generate_voice', Path(__file__).with_name('generate_voice.py'))
+voice = importlib.util.module_from_spec(SPEC)
+SPEC.loader.exec_module(voice)
+
+
+class VoiceHistoryTests(unittest.TestCase):
+ def setUp(self):
+ self.temp = tempfile.TemporaryDirectory()
+ self.root = Path(self.temp.name)
+ self.catalog = {'schemaVersion': 1, 'clips': [
+ {'id': 'count_01', 'text': '하나', 'usage': 'count', 'stageIds': [1], 'required': True},
+ {'id': 'guide_collect', 'text': '친구를 찾아 끌어와 볼까?', 'usage': 'guide', 'stageIds': [1], 'required': True}]}
+ self.profile = {'schemaVersion': 1, 'modelId': voice.MODEL_ID, 'modelRevision': 'a' * 40,
+ 'language': 'Korean', 'speaker': 'Sohee', 'instruct': '천천히 읽어 주세요.',
+ 'device': 'cuda:0', 'dtype': 'bfloat16', 'attention': 'sdpa', 'seed': 42,
+ 'generationParameters': {'max_new_tokens': 2048}}
+ self.calls = []
+
+ def tearDown(self):
+ self.temp.cleanup()
+
+ def fake(self, clip):
+ self.calls.append(clip['id'])
+ return np.sin(np.linspace(0, 20, 2400)).astype(np.float32) * .2, 24000
+
+ def run_generation(self, catalog=None, profile=None, ids=None):
+ return voice.generate(catalog or self.catalog, profile or self.profile, self.root,
+ ids=ids, synthesize=self.fake, environment={'test': True})
+
+ def test_partial_changed_clip_regenerates_and_preserves_original(self):
+ first = self.run_generation()
+ old = (self.root / first['clips'][0]['file']).read_bytes()
+ revised = copy.deepcopy(self.catalog)
+ revised['clips'][1]['text'] = '친구를 끌어와 볼까?'
+ second = self.run_generation(catalog=revised)
+ self.assertEqual(['reused', 'generated'], [c['result'] for c in second['clips']])
+ self.assertEqual(['count_01', 'guide_collect', 'guide_collect'], self.calls)
+ self.assertEqual(old, (self.root / first['clips'][0]['file']).read_bytes())
+ self.assertNotEqual(first['runId'], second['runId'])
+ self.assertEqual([], voice.validate_manifest(second, revised, self.profile, self.root))
+
+ def test_empty_text_duplicate_ids_and_bad_stage_rejected(self):
+ for edit in ('empty', 'duplicate', 'stage'):
+ bad = copy.deepcopy(self.catalog)
+ if edit == 'empty': bad['clips'][0]['text'] = ' '
+ if edit == 'duplicate': bad['clips'][1]['id'] = 'count_01'
+ if edit == 'stage': bad['clips'][0]['stageIds'] = [31]
+ with self.assertRaises(ValueError): self.run_generation(catalog=bad)
+ self.assertEqual([], self.calls)
+
+ def test_missing_corrupt_and_profile_mismatch_cannot_validate(self):
+ manifest = self.run_generation()
+ changed = copy.deepcopy(self.profile)
+ changed['instruct'] = '밝게 읽어 주세요.'
+ self.assertTrue(voice.validate_manifest(manifest, self.catalog, changed, self.root))
+ wav = self.root / manifest['clips'][0]['file']
+ wav.write_bytes(b'not wav')
+ self.assertTrue(voice.validate_manifest(manifest, self.catalog, self.profile, self.root))
+ wav.unlink()
+ self.assertTrue(voice.validate_manifest(manifest, self.catalog, self.profile, self.root))
+
+ def test_partial_scope_does_not_claim_all_required(self):
+ manifest = self.run_generation(ids=['count_01'])
+ self.assertEqual('selected', manifest['scope'])
+ self.assertEqual([], voice.validate_manifest(manifest, self.catalog, self.profile, self.root, ['count_01']))
+ self.assertTrue(voice.validate_manifest(manifest, self.catalog, self.profile, self.root))
+
+ def test_failed_or_invalid_waveform_not_success(self):
+ def broken(clip): return np.array([np.nan]), 24000
+ manifest = voice.generate(self.catalog, self.profile, self.root, synthesize=broken)
+ self.assertEqual(['failed', 'failed'], [c['result'] for c in manifest['clips']])
+ self.assertTrue(voice.validate_manifest(manifest, self.catalog, self.profile, self.root))
+
+ def test_changed_profile_and_tampered_waveform_force_regeneration(self):
+ first = self.run_generation()
+ path = self.root / first['clips'][0]['file']
+ sf.write(path, np.zeros(2400), 24000)
+ second = self.run_generation()
+ self.assertEqual(['generated', 'reused'], [c['result'] for c in second['clips']])
+ revised = copy.deepcopy(self.profile)
+ revised['seed'] = 43
+ third = self.run_generation(profile=revised)
+ self.assertEqual(['generated', 'generated'], [c['result'] for c in third['clips']])
+
+ def test_unknown_requested_id_rejected(self):
+ with self.assertRaises(ValueError): self.run_generation(ids=['missing'])
+
+ def test_pcm_export_resamples_and_preserves_existing_runtime(self):
+ import sys
+ sys.path.insert(0, str(Path(__file__).parent))
+ from prepare_voice import prepare
+ manifest = self.run_generation()
+ target = self.root / 'runtime'
+ selection = prepare(manifest, self.catalog, self.profile, self.root, target)
+ info = sf.info(target / 'count_01.wav')
+ self.assertEqual((44100, 1, 'PCM_16'), (info.samplerate, info.channels, info.subtype))
+ self.assertAlmostEqual(.1, info.duration)
+ self.assertEqual('not_listened', selection['selections'][0]['review'])
+ original = (target / 'count_01.wav').read_bytes()
+ sf.write(target / 'count_01.wav', np.ones(4410) * .1, 44100)
+ changed = (target / 'count_01.wav').read_bytes()
+ with self.assertRaises(ValueError): prepare(manifest, self.catalog, self.profile, self.root, target)
+ self.assertEqual(changed, (target / 'count_01.wav').read_bytes())
+ self.assertNotEqual(original, changed)
+
+
+if __name__ == '__main__':
+ unittest.main()